Browse categories
Explore
Fiverr Pro
English
$
USD

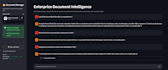
Are generic AI bots hallucinating on your critical business data?
I architect, deploy, and harden production-grade Retrieval-Augmented Generation (RAG) pipelines and private document AI systems that ground frontier LLMs in your proprietary knowledge base.
Whether using cloud vector stores or 100% private, on-premise Docker deployments running local open models, your sensitive data remains accurate, verifiable, and secure behind your firewall.
Architectural Capabilities:
All pipelines feature strict prompt guardrails and source citations.
Please message me before ordering to align on your data schemas and security constraints.
AI Solutions Architect, RAG and Automation Specialist
Languages
How do we prevent the AI from hallucinating?
We implement strict system guardrails, hybrid search (semantic vector + BM25 keyword matching), and reranking models. The LLM is strictly constrained to synthesize answers only from the retrieved chunks, returning verified source citations.
Can this system run 100% privately without sending data to third parties?
Yes. I can deploy an air-gapped, containerized pipeline via Docker on your private VPS or local hardware using high-performance open-weight models, ensuring zero proprietary data leaves your environment.
Which document formats can the pipeline ingest?
The pipeline handles standard and complex layouts including unstructured PDFs, scanned documents via OCR, Word documents (.docx), spreadsheets (.csv, .xlsx), markdown, and database dumps.


