Browse categories
English
$
USD
Connect to your AI
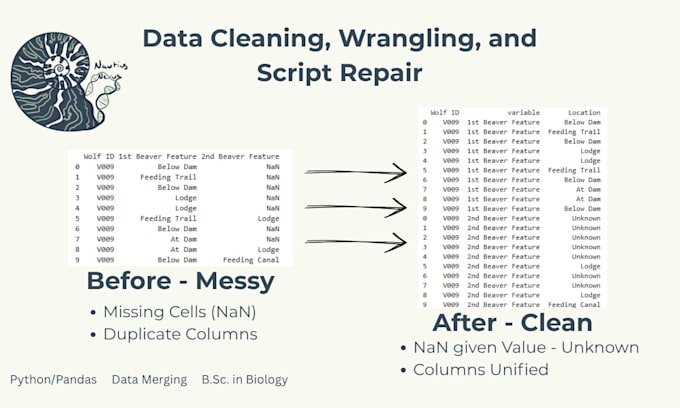
Are you a graduate student, researcher, or academic struggling with broken code or a messy dataset? As a data analyst with a B.S. in Biology and a minor in Psychological Science, I understand that your data represents hours of meticulous observations and physical work, and are not just corporate spreadsheets. I specialize in the mechanical execution of data cleaning so you can focus entirely on your thesis, committee guidelines, or other pressing matters.
What I Do:
Code Debugging: Clearing syntax errors, loops, or layout warnings out of your Jupyter Notebooks.
Data Wrangling: Restructuring raw formats, handling missing cells, and normalizing text categories.
Multi-Stream Integration: Synchronizing up to 3 separate logs or spreadsheets into a single, unified dataset.
Please Note: To protect data integrity, your raw file and research hypotheses are frozen once the order begins.
For massive datasets exceeding the baseline row thresholds, please apply the 'Extra Data or File' extra at checkout. For an additional project notebook, select same. If you would like an explanation of code, select 'Code Documentation'.
Review my public code at github.com/skyegambrel
What specific file formats do you accept for data cleaning?
I accept standard tabular data formats including CSV, XLSX (Excel), TSV, and TXT files, as well as Jupyter Notebook script files (.ipynb) for debugging. Please ensure your file structures are unencrypted before uploading them to the requirements panel.
What counts as a single "Item Cleaned" or dataset file?
A single item refers to one standalone spreadsheet, data table, or source code notebook. Tier 1 covers a single broken script file, Tier 2 covers a single raw data file (up to 200 rows), and Tier 3 covers the cleaning and structural integration of up to 3 separate files.
How do you handle missing values, blank cells, or NaNs in my dataset?
• I use specialized Python libraries (Pandas and NumPy) to isolate missing data patterns. Depending on your explicit instructions, I will write clean pipelines to drop empty rows, isolate structural gaps, or impute missing categories based on your project requirements—without fabrications.
Will you explain the Python code or libraries you used to clean my files?
The base tiers deliver the clean data file and your annotated script. If you need a comprehensive, line-by-line plain English explanation of the exact Pandas functions used so you can easily defend the data pipeline to your committee, please select the "Code Documentation" extra at checkout.
Do you sign Non-Disclosure Agreements (NDAs) or data privacy clauses?
As per Fiverr's strict, secure platform confidentiality rules, your raw source files, observation notes, and hypotheses are treated as strictly confidential proprietary intellectual property and are never shared or published.
