Browse categories
Explore
Fiverr Pro
English
$
USD
Need a reliable backend architecture for an AI document chat system?
What I can build
I can design around issues such as:
Send me your document types, expected page volume, and preferred technology stack, and I will help map out the backend pipeline.
Your AI System Built Right From Day One
Languages
Can you build a chatbot that answers questions from my PDF documents?
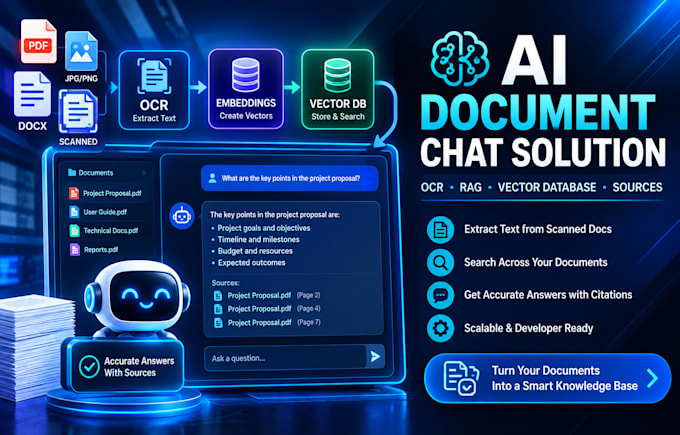
Yes. I can build a document-chat system where users upload PDFs and ask questions, with answers generated from the document content.
What if my PDFs are scanned and have no selectable text?
I can add an OCR pipeline to extract text from scanned and image-based PDFs before processing them for AI search and chat.
My AI chatbot gives answers that are not actually in my documents. Can you fix this?
Yes. I can design a RAG pipeline with better document chunking, retrieval, metadata, and source grounding to reduce unsupported answers.
Can the chatbot show me where an answer came from?
Yes. The system can return source information such as the document name, page number, section, or retrieved text alongside the answer.
I have thousands of documents. Can they all be searchable with AI?
Yes. I can design a scalable ingestion, embedding, and vector-search architecture for large document collections.
My scanned documents contain tables, columns, or unusual layouts. Will OCR still work?
These layouts can cause extraction problems. I can design preprocessing and validation steps to handle common OCR failure points and improve the quality of extracted content.
