Browse categories
Explore
Fiverr Pro
English
$
USD
Data Engineer
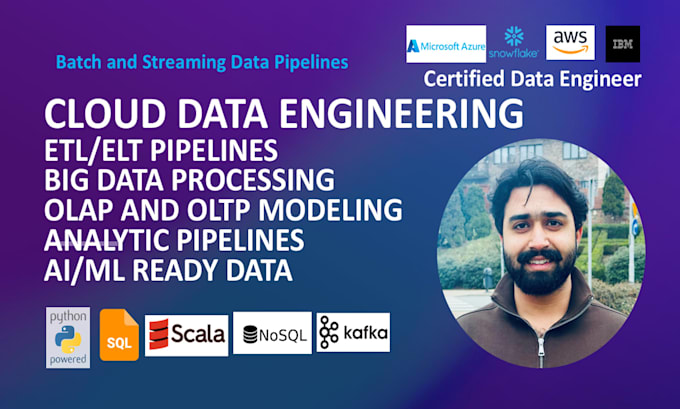
Need a Senior Data Engineer for scalable ETL/ELT pipelines, Big Data processing, Data Warehousing, or Lakehouse architectures?
I'm Muhammad Ahmed, a Data Engineer with 4+ years of experience building enterprise-grade data platforms across AWS, Azure, GCP, and Snowflake ecosystems.
Services I Offer:
Technologies:
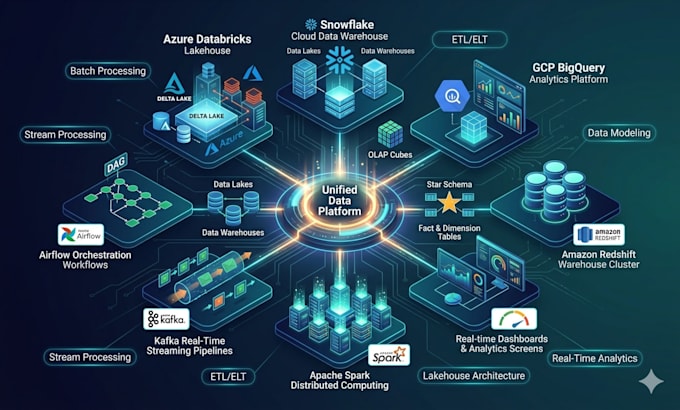
Azure Databricks, Snowflake, GCP BigQuery, Amazon Redshift, Apache Spark, PySpark, Kafka, Airflow, DBT, Snowflake SQL, SparkDF, PostgreSQL, AWS, Docker, Python, SQL.
I build scalable, reliable, and cloud-native data engineering solutions for analytics, reporting, automation, and real-time processing. And provide AI/ML and analytics ready data.
Data Engineering, ETL, ELT, Big Data, PySpark, Airflow, Kafka, Snowflake, Databricks, Data Warehouse, Redshift, BigQuery.
Warehouse Platform:
Snowflake
•
BigQuery
•
Databricks
Project Type:
New Build
Which cloud platforms do you support?
I work with AWS, Azure, GCP, Snowflake, Databricks, Amazon Redshift, and BigQuery.
Do you build batch and streaming pipelines?
Yes. I develop batch pipelines using Apache Spark and streaming solutions using Kafka and Spark Streaming.
Can you design Data Warehouse and Lakehouse architectures?
Yes. I design scalable Data Lakes, Data Warehouses, and Lakehouse systems using Medallion Architecture and modern cloud platforms.
Which orchestration tools do you use?
Apache Airflow, Snowflake Tasks/Scheduled Jobs, and cloud-native scheduling solutions.
Do you implement data modeling?
Yes. I work with Star Schema, Snowflake Schema, Dimensions, Fact Tables, OLAP, and OLTP modeling.
Which technologies do you use for data processing?
PySpark, Spark SQL, DBT, Snowflake SQL, SparkDF, Python, SQL, Kafka, and cloud-native processing tools.
Can you optimize existing pipelines?
Yes. I can improve performance, scalability, cost optimization, and reliability of existing data engineering systems.