Browse categories
Explore
Fiverr Pro
English
$
USD

Your documents contain valuable knowledge. Your team can't find it fast enough.
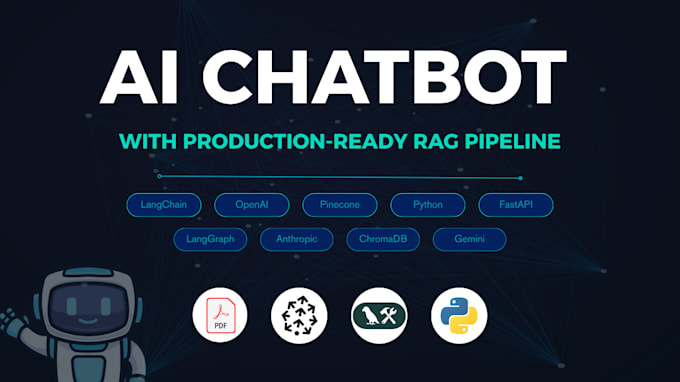
Most RAG implementations fail in production because they're built for demos.
I take a diagnostic approach: chunking strategy, embedding model, and
retrieval tuned specifically for your documents and use case.
WHAT YOU GET
Fully functional RAG pipeline (Python-based)
Vector store setup (Chroma, Pinecone, or Weaviate)
Chunking and retrieval tuned for your document structure
Clean, documented code you can maintain
Technical handoff document
7 days post-delivery support for bugs and integration questions
GOOD FIT
PDFs, docs, or text files you want to query in natural language
Internal assistant or customer-facing chatbot
Existing RAG prototype that isn't performing well
NOT A GOOD FIT
Real-time / live web scraping pipelines
Full-stack app with frontend UI
Ready-to-use web application or hosted chatbot interface
(this gig delivers backend code, not a deployed product)
Before starting, I ask a few questions to understand your documents, use case,
and performance requirements. The right solution depends on the diagnosis.
Message me before ordering if you're unsure which package fits.
AI Engineer
Languages
Do you work with documents in Spanish or other languages?
Yes. I select embedding models appropriate for your document language. Multilingual pipelines are supported.
What LLM does the pipeline use?
OpenAI (GPT-4o/3.5), Anthropic (Claude), Google (Gemini), or open-source models depending on your preference and budget. We align this before starting.
Do I need technical knowledge to use the delivered system?
No. Every delivery includes a handoff document written for non-technical users, plus a short walkthrough video on request.
Can you improve a RAG system I already built?
Yes. Message me with details about your current setup and the problems you're experiencing.
What if my documents are confidential?
You can share a sanitized sample for development. The final system runs on your infrastructure or your API keys your data never passes through third parties.
