Browse categories
Explore
Fiverr Pro
English
$
USD
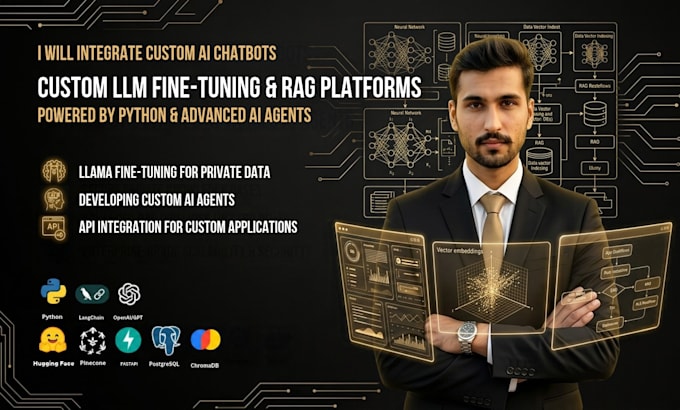
Are you struggling to make AI actually work for your business?
Integrating a Large Language Model isn't just about calling an API. Generic setups often struggle with hallucinations, slow response times, poor data retrieval, and a lack of domain-specific knowledge, causing them to fall short in real-world applications.
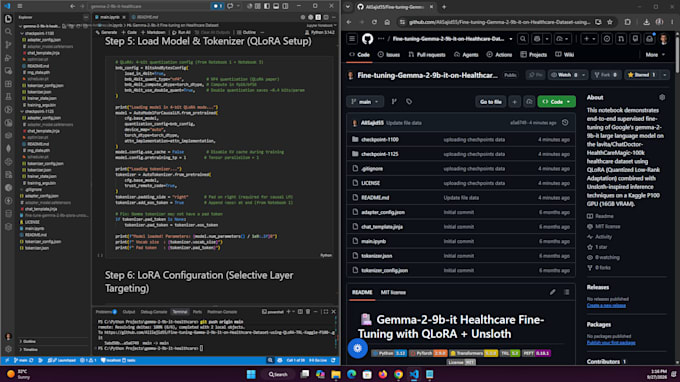
I'm an AI Engineer specializing in custom LLM integration, advanced RAG architectures, and model fine-tuning, turning complex AI capabilities into production-ready software.
What I Offer:
Stop settling for generic AI outputs. Let's build a fast, precise AI solution for your business.
Message me to discuss your idea.
AI Engineer Deep Learning Computer Vision GEN AI Agentic AI
Languages
What LLM models do you support for integration and fine-tuning?
I work with both commercial APIs like OpenAI (GPT-4o), Claude, and Gemini, as well as open-source LLMs like Llama 3, Mistral, and Falcon for custom fine-tuning and hosting.
What is the difference between LLM Integration and Fine-Tuning?
Integration connects existing pre-trained models (like OpenAI) to your app via APIs to handle general tasks. Fine-tuning involves training an open-source model on your specific custom dataset so it learns your domain knowledge and internal guidelines directly.
Do I need to provide my own API keys or server infrastructure?
Yes, you will need to provide your own API keys (e.g., OpenAI, Anthropic) or hosting infrastructure (AWS, GCP, RunPod) for model deployment. However, I can guide you on setting these up efficiently.
Can you build a custom RAG system with private document search?
Absolutely! I can set up a Retrieval-Augmented Generation (RAG) pipeline using LangChain, LlamaIndex, and vector databases (like Pinecone, Supabase, or Qdrant) so your model accurately answers queries from your private documentation or knowledge base.
Will I receive the complete source code and documentation?
Yes, all packages include clean, well-commented source code along with complete documentation and instructions on how to run, test, and deploy the application.