Browse categories
Explore
Fiverr Pro
English
$
USD

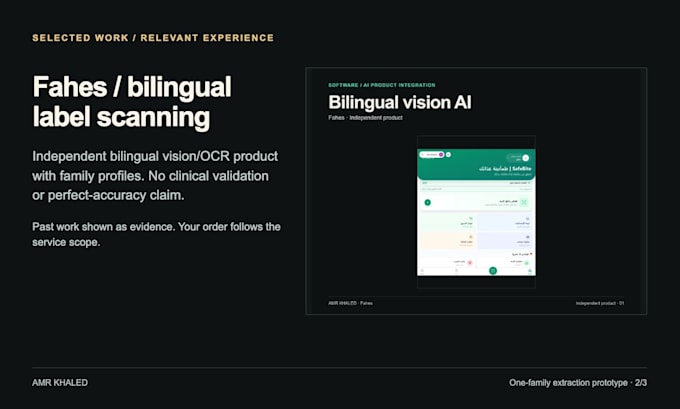
Build a runnable AI extraction prototype for one agreed input family: text-based PDFs OR product-label images.
Scope: up to 12 fields, ten authorized supplied examples, one agreed API/model provider and one demo interface. PDFs are limited to ten pages per sample; label images to 10 MB each.
You receive the extraction demo, validated JSON structure, comparison against your supplied expected outputs, documented failures/limits, source code and setup instructions. One correction round covers the agreed schema and examples.
Provide a field schema, non-sensitive or synthetic samples with expected outputs, demo language, provider preference and agreement on client-paid API usage. Share access through the permitted contract workflow.
Acceptance: the prototype runs with the documented setup, returns the agreed structure and includes an honest evaluation on the supplied examples. No perfect-accuracy or clinical-validation promise. Production deployment, extra document families and recurring operation need separate scope. Delivery: 21 calendar days after complete inputs.
Full Stack Developer and Product Motion Designer
Languages
What inputs are included?
One agreed input family: text-based PDFs up to ten pages each OR product-label images up to 10 MB each, with ten supplied examples.
Will extraction always be correct?
No. The prototype includes validation and an honest evaluation against the supplied expected outputs, with known failures documented.
Is this production deployment?
No. It includes a runnable prototype, source, setup and evaluation. Production deployment, ongoing operation and more input families are separate.