Browse categories
English
$
USD
Connect to your AI

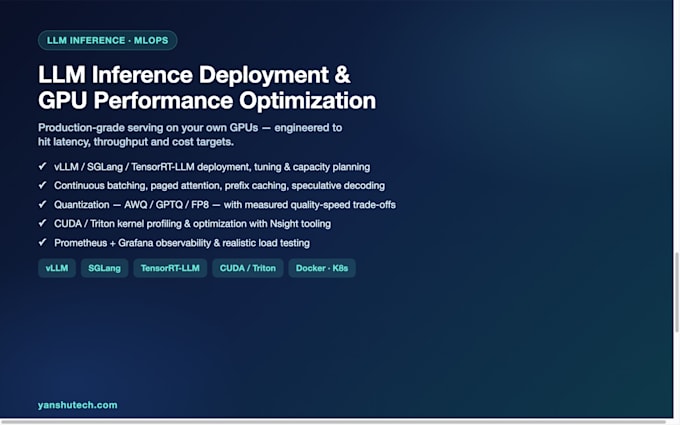
Bring your model latency down and throughput up - with measurable numbers.
Typical work:
- Serve your model with vLLM, SGLang or TensorRT-LLM, tuned for your GPU fleet
- Continuous batching, paged attention, prefix caching, speculative decoding
- Quantization (AWQ / GPTQ / FP8) with a quality-vs-speed comparison you can verify
- CUDA / Triton profiling with Nsight to find real bottlenecks
- Docker / Kubernetes packaging, Prometheus + Grafana dashboards, realistic load tests
What you get: serving configs, benchmark results (p50/p95 latency, tokens/sec, cost per 1M tokens), a load-test report and a short runbook your team can operate.
What is NOT included: GPU hardware and cloud spend, model licensing, paid third-party services, 24/7 on-call support. Everything runs on your infrastructure.
17 years of systems and ML engineering; I deploy models on customer GPUs as part of my daily product work.
Send me your model size, GPU type and target numbers before ordering.
Languages
Will this work with my GPU and model?
Yes - A100, H100, L40S, RTX 4090 and any Hugging Face model. I benchmark on your actual hardware before tuning, so you get real numbers for your setup.
