Browse categories
English
$
USD
Connect to your AI


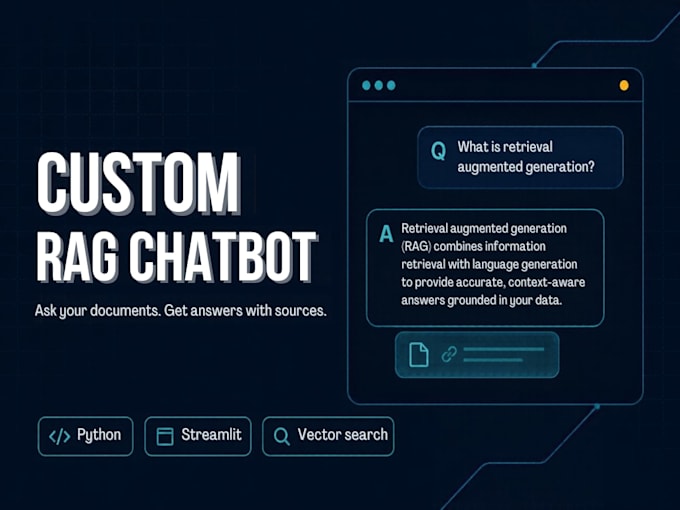
Your answers are buried in PDFs, handbooks, and wikis. I build a custom RAG (Retrieval-Augmented Generation) assistant in Python so you can ask plain-English questions and get answers grounded in your own documents, with sources.
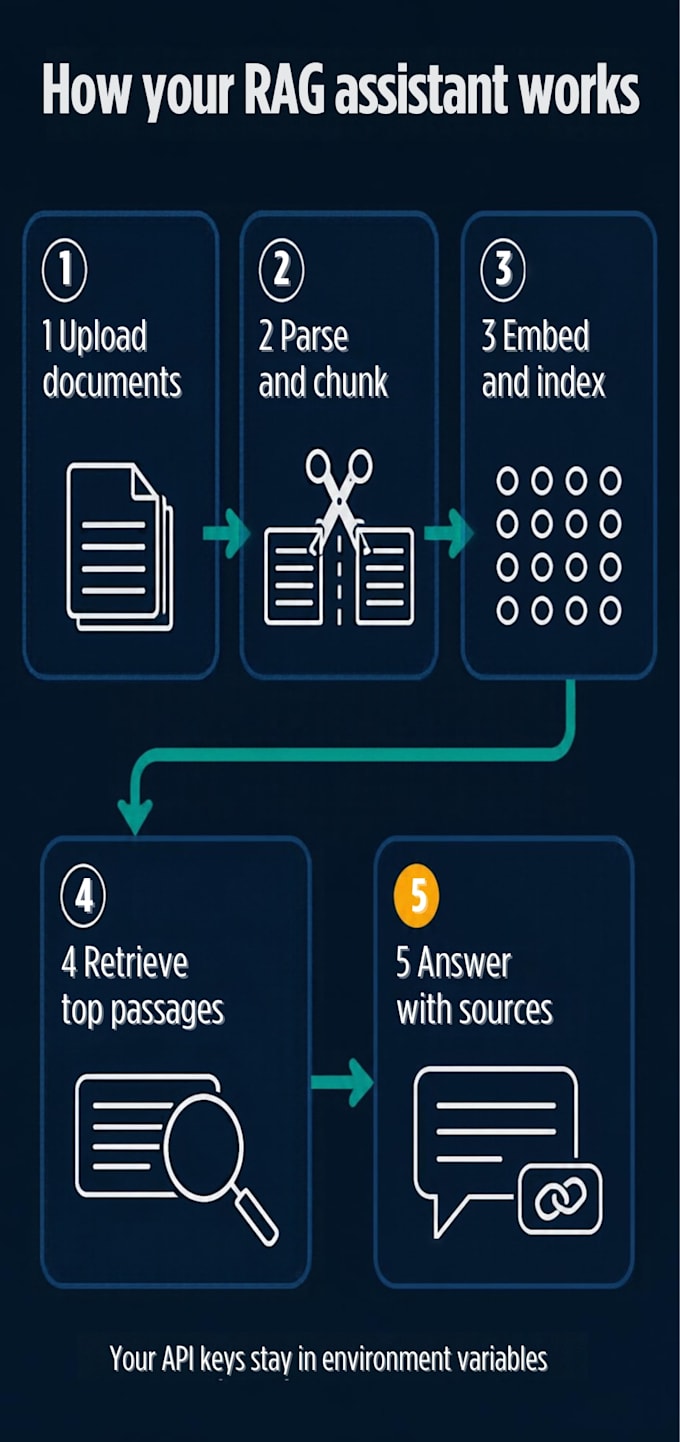
HOW IT WORKS
1. You share your use case and sample documents
2. I ingest, parse, and chunk your files
3. Text is embedded and stored in a vector database (FAISS or Chroma)
4. Each question retrieves the most relevant passages
5. An LLM (OpenAI, Anthropic, or compatible open-source) answers from them and cites sources
WHAT YOU GET
- Python source code and setup guide
- Streamlit interface (simple in Basic)
- Source citations on answers
- Retrieval testing on sample questions
- API keys kept in environment variables, never hard-coded
BEST FOR
Startups, SaaS, HR, support teams, consultants, agencies, researchers.
PROTOTYPE VS PRODUCTION
Packages deliver a working, tested assistant. Authentication, scaling, and compliance are scoped separately.
HONEST NOTE
RAG reduces unsupported answers but cannot guarantee 100% accuracy. I test retrieval on your documents.
Message me your use case and sample files first, and I will confirm scope and price.
Python Data Analyst, Pandas, NumPy, Matplotlib Expert, Scikit Learn, Tensorflow
Languages
What is RAG?
Retrieval-Augmented Generation. The app first finds the most relevant passages in your documents, then asks an AI model to answer using only those passages, so answers are tied to your content.
Which file formats can be supported?
PDF, DOCX, TXT and Markdown are standard. HTML and CSV are available in Premium. Scanned PDFs need OCR, which is a custom offer.
Can the assistant answer from my company documents?
Yes. It retrieves from the files you provide and answers from them. If the documents don't contain the answer, it is designed to say so rather than guess.