Browse categories
Explore
Fiverr Pro
English
$
USD
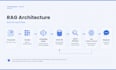
Most "RAG chatbots" on Fiverr ship as demos:
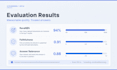
one PDF, weak chunking, no retrieval evaluation, hallucinations everywhere.I build production-grade RAG systems engineered to ship cited, evaluated, monitored.
WHAT I'LL BUILD:
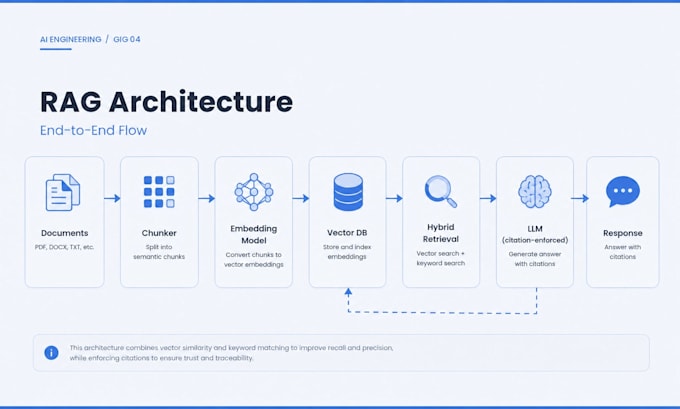
Custom RAG architecture (LangChain, LlamaIndex, or raw Python) Vector database setup (Pinecone, Qdrant, Weaviate, pgvector, Chroma) Smart chunking + embedding pipeline (OpenAI, Cohere, BGE) Hybrid retrieval dense + sparse + reranking for actual recall@k Citation enforcement every claim traces to a source chunk Multi-model orchestration (Claude, GPT-4o/5, Gemini) Evaluation framework (Ragas, custom evals) you know it works Observability (LangSmith or custom logging) FastAPI / Node API endpoint ready for your app Self-hosted (Docker, your VPS) or managed (Pinecone)
WHO I BUILD FOR:
SaaS founders adding AI search / Q&A Dev teams needing RAG that survives production Internal knowledge bases (Notion, Confluence, S3) Startups replacing keyword search with semantic
WHY HIRE ME:
RAG that doesn't hallucinate evaluated, cited, monitored Clean documented code your team can maintain 1-hour response time Send your docs + use case. Scoped plan in 1 hour.
AI Voice Agent Developer, Vapi, Bland AI, Twilio, GPT4o
Languages
What's the difference between a "demo RAG" and a "production RAG"?
A demo RAG embeds one PDF, retrieves top-k chunks, and prompts an LLM — it works on tutorial documents and breaks on real data. A production RAG has smart chunking tuned to your domain, hybrid retrieval (not just cosine similarity), reranking, citation enforcement, evaluation against ground-truth Q/
Which vector database should I use — Pinecone, Qdrant, Weaviate, or pgvector?
Pinecone is fastest to deploy (managed, zero ops) — best when you want to ship in days. Qdrant self-hosted is the best free option that scales. Weaviate is strong on hybrid search with metadata filtering. pgvector is right when you already have Postgres and want vectors next to your relational data.
How do you prevent hallucinations?
Three layers. (1) Citation enforcement — the LLM must cite the retrieved chunk for every claim, and outputs without citations are flagged. (2) Retrieval validation — confidence scores on retrieval, so low-confidence questions return "I don't have enough information" instead of guessing. (3) Cross-mo
Can you self-host the entire system on my infrastructure?
Yes. Full Docker compose setup: Qdrant or Weaviate for vectors, FastAPI for the service, your choice of LLM endpoint (OpenAI API, Anthropic API, or self-hosted Llama/Mistral via Ollama or vLLM). Useful when you have compliance constraints or don't want vendor lock-in. Included from Standard tier up.