Browse categories
Explore
Fiverr Pro
English
$
USD
AI Full Stack Developer specializing in LLM and RAG optimization
Your team needs data from the web, but the pages are JavaScript heavy, sit behind logins, and change every month. Off the shelf scrapers break within days.
I build browser automation with Playwright that keeps running in production - scheduled, monitored, and handed over with full source code, not a one off script.
WHAT YOU GET
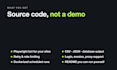
- Playwright bot targeting your sites, in Python or Node
- Clean CSV, JSON, or direct database output
- Retry, rate limiting, and anti block handling
- Login, session, and proxy support
- Source code and a README you can run yourself
HOW IT WORKS
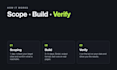
1) Scoping, 1 day. I check your target sites and confirm what is reachable.
2) Build, 3 to 14 days. Script, output format, and test runs on real pages.
3) Verification. I run the bot on your data and show you the results.
THIS IS NOT FOR YOU IF
- The target site prohibits automated access in its terms. I will not bypass that.
- You need a single throwaway export of 50 rows. A manual copy is cheaper.
I work as an AI full stack developer across Go, TypeScript, and Python, so the bot can be wired into your backend instead of left as a standalone script.
Technology:
JavaScript
•
Python
•
Nodejs
•
Playwright
•
Golang
Technique:
Other
Do I get the source code?
Yes, everything. Repository handover is included and there is no extra license fee.
Can you work with a site that needs a login?
Yes. I handle sessions, cookies, and proxies, as long as you have the right to access the data.
Python or Node?
Either. I default to Python for data heavy jobs and Node when the bot has to live inside an existing JavaScript backend.
Can it run on a schedule?
Yes. I can ship it Dockerized with a cron or CI schedule, plus alerts when a run fails.
Will the bot keep working if the site changes?
Selectors sit in one config file, so they are cheap to update. In scope fixes are free for 2 weeks after delivery.
Do you scrape any site?
No. I check the terms and robots policy first, and I will tell you up front if a target is off limits.


