Browse categories
English
$
USD
Connect to your AI

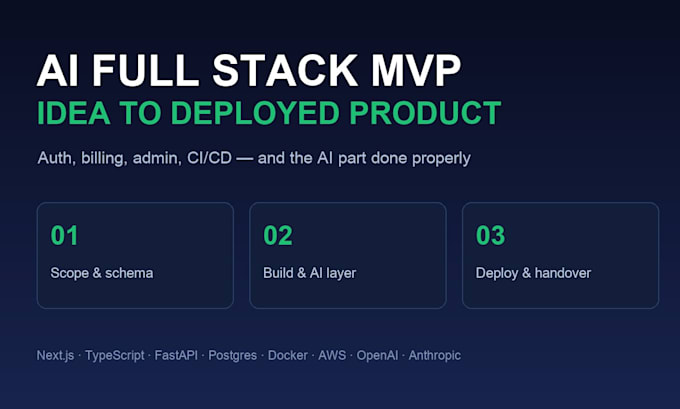
I take your idea from a blank repo to a deployed AI product that real users can log into.
What you get
- Next.js + TypeScript frontend, typed API, Postgres schema and migrations
- Auth, billing, roles, admin panel and transactional email wired up
- The AI part done properly: streaming responses, tool calling, structured output, retries, cost and latency budgets
- Dockerised deploy, CI pipeline, error tracking and a handover document
Why me
I ship LLM products in production, not demos. Recent measured results: 70% lower p95 latency, 38% lower serving cost, 49% fewer output tokens, and a 125x speedup on a core listing path.
Stack
TypeScript, Next.js, React, Tailwind, Node, FastAPI, Python, Postgres, Supabase, Redis, Docker, AWS, OpenAI / Anthropic / vLLM.
Tell me what the product should do on day one and who it is for. I will reply with a scope, a timeline and the exact package that fits before you order.
AI Full Stack Developer specializing in LLM and RAG optimization
Languages
