Browse categories
English
$
USD
Connect to your AI
Full Stack, Backend and Data Engineer
Turn digital PDFs and scanned forms into structured data your team can use.
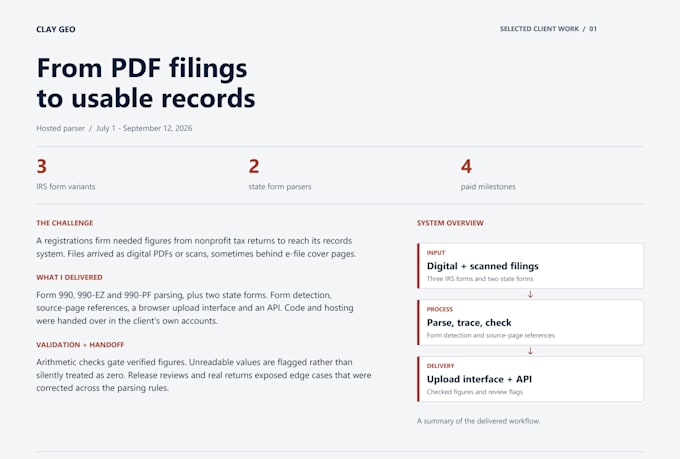
I build reusable Python extraction workflows for agreed document layouts, with CSV or JSON output and checks for missing or invalid fields. A completed client project included a custom PDF data parser.
Basic covers one digital PDF layout. Standard adds OCR for reviewed scanned documents. Premium adds more layouts and one extraction API endpoint for your application. Every package includes source code, sample output, source-page references, validation flags and setup/handoff notes.
I review representative samples first, agree on the fields and expected results, then test the parser against that sample set. OCR results depend on document quality; the workflow flags detected exceptions for review.
Packages cover the stated layouts, total fields and initial test pages. Send sample documents and your desired output before ordering. Larger archives, complex tables, highly variable layouts or additional integrations can be quoted separately. Hosting and third-party processing fees are separate.


Technology:
Python
What counts as a layout or a field?
A layout is one consistent document template. A field is one output column or JSON key; field limits are total across the agreed schema. Complex tables or major template variations need separate review.
Can you process scanned PDFs and handwriting?
Standard and Premium include OCR for reviewed scans. Handwriting, degraded pages and highly variable layouts need sample review and may require a custom scope.
How do you check extraction quality?
I compare output with agreed sample values and report the results. Missing or invalid values receive validation flags. OCR can make errors, so I do not promise perfect accuracy.
What is included in delivery and revisions?
Source code, sample output, source-page references, validation flags and setup notes. Premium adds one API endpoint. Revisions refine the agreed extraction; new layouts, fields or integrations are additional scope.