Browse categories
Explore
Fiverr Pro
English
$
USD
I build automations that save time and reduce manual work
Level 1
Has met certain performance criteria and shows strong potential in the marketplace.
I will build an automated data pipeline that collects, cleans, transforms, and sends your business data where it needs to go.
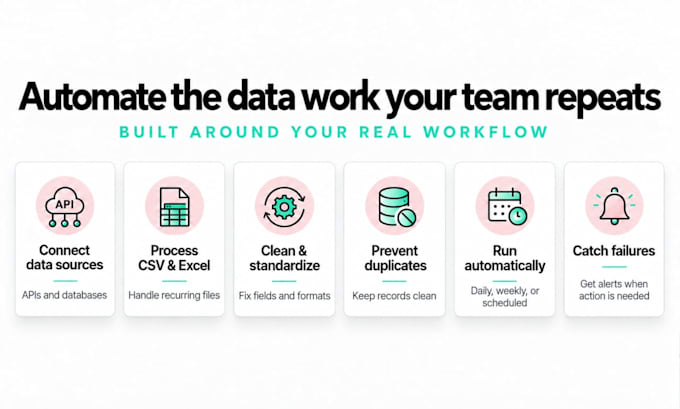
I can work with APIs, CSV, Excel, JSON, PostgreSQL, MySQL, Supabase, cloud storage, and other compatible systems.
Depending on the package, your pipeline can include:
Data extraction and API connections
Cleaning, mapping, filtering, and deduplication
Validation and data-quality checks
Scheduled automatic runs
Error logging and failure alerts
Tests, documentation, and deployment
This service is ideal for recurring data tasks, reporting workflows, database updates, and system-to-system data movement.
Please message me before ordering with your data source, destination, sample data, and the process you want to automate so I can confirm the right package.


Tools & Platforms:
Other
What is a data pipeline or ETL pipeline?
It is an automated process that collects data from one source, cleans or transforms it, and sends it to another system. For example: API → clean and validate data → PostgreSQL.
What data sources can you work with?
Common sources include REST APIs, CSV, Excel, JSON, PostgreSQL, MySQL, Supabase, cloud storage, and other systems with accessible APIs or database connections.
Can the pipeline run automatically?
Yes. Standard and Premium packages can include scheduled runs such as hourly, daily, or weekly processing
Can you clean, combine, or transform my data?
Yes. This can include renaming fields, formatting dates, filtering records, removing duplicates, joining datasets, converting values, and applying business rules.
Can you connect an API to my database?
Usually yes. Please send me the API and destination details before ordering so I can confirm access and feasibility.
What happens if the pipeline fails?
Depending on the package, I can include logging, validation, failure alerts, retry logic, and other error-handling measures.
Will I receive the source code and documentation?
Yes. The agreed source code and setup documentation are included so you are not locked into the delivery.
What types of projects are not included in these packages?
Large enterprise data warehouses, Spark or Databricks architecture, Kafka-scale streaming, major migrations, and other complex data-engineering systems require separate scoping and a custom offer.
Should I contact you before ordering?
Yes. Please message me first with your data source, destination, sample data, and desired workflow so I can confirm the correct package and scope.