Browse categories
Explore
Fiverr Pro
English
$
USD
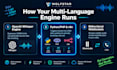
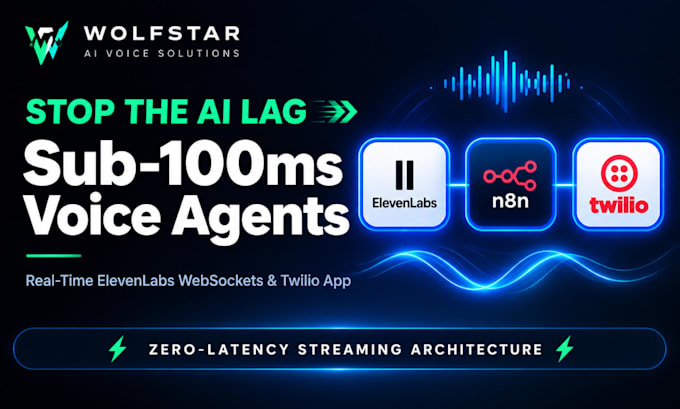
Is a slow, lagging 4-second delay ruining your AI voice agent experience? Are your voice bots failing to execute real-time actions during live phone calls?
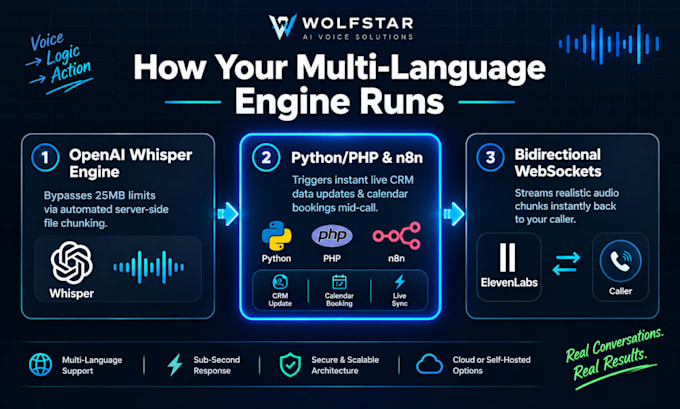
With custom 11Labs Whisper Python/PHP backend code, advanced server architecture, I deliver zero-latency voice agents that can read database variables, update CRM live on the call, and handle massive datasets without hitting standard API limits.
Advanced Technical Architecture You Get:
Sub-100ms WebSockets Streaming
Bypassing the Whisper 25MB Limit
Live Mid-Call Function Calling
Phonetic Injection Pre-Processing
contact me!
Software Engineer With Ai Dev Mobile App website dev bot VA Ai voice agents
Languages
How do you achieve sub-second response latency?
Instead of waiting for full sentences to complete, I build bidirectional WebSockets connections in Python or Node.js. This streams audio packets back and forth simultaneously, dropping latency below 1.5 seconds.
How do you bypass OpenAI Whisper’s 25MB file limit?
I build an automated server-side file handler using FFmpeg. When a massive audio file is uploaded, the script slices it into optimized, overlapping 20MB chunks, passes them to Whisper concurrently, and seamlessly stitches the transcripts together.
What is mid-call function calling?
It allows the AI voice agent to interact with your software while talking. If a customer wants to change their appointment time, the agent triggers a live background webhook to update your database instantly during the phone call.
How do you prevent the AI from mispronouncing industry terms or company names?
I implement a custom text-pre-processing script layer. Before the text hits the ElevenLabs API, any specialized jargon or acronyms are systematically rewritten into Phonetic Spelling Equivalents to force correct pronunciation.
Can this setup run completely self-hosted?
Yes! If you want to avoid recurring API token charges, I can help you configure Dockerized, self-hosted Whisper containers directly inside your own server environment to process infinite audio text conversions for free.
Do I need an n8n cloud account, or can we use a self-hosted instance?
Either works perfectly. I can deploy your workflows onto an n8n Cloud account or set up a self-hosted n8n instance on your VPS (like DigitalOcean or AWS) to maximize security and eliminate monthly workflow execution caps.
Can your streaming agent handle sudden user interruptions?
Yes. I optimize the Voice Activity Detection (VAD) endpointing matrices. The millisecond the server detects the human user speaking over the AI, the streaming audio pipeline stops instantly to listen to the new input.
What database frameworks do you natively support?
I routinely connect voice apps to PostgreSQL, MongoDB, MySQL, Firebase, and cloud CRM tables (like Airtable, GoHighLevel, and HubSpot Hubs) using native backend integrations.
Will the system work with custom voice clones I've already made?
Absolutely. We just feed your specific ElevenLabs Voice ID directly into our WebSocket streaming script parameters, and the system will run your custom voice clone instantly.
Will the cloned voice sound natural when translating from English to languages like Spanish or Arabic, creole, mandarin, swedish, Portuguese etc?
Absolutely. By leveraging ElevenLabs' advanced multilingual models, the voice maintains its foundational throat timbre, age characteristics, and conversational inflections while adopting native accent flowing rules.