Browse categories
English
$
USD
Connect to your AI

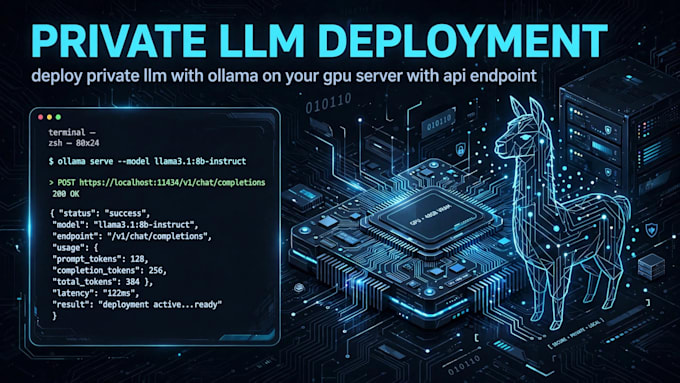
Want your own private AI model running 24/7? I install Ollama (or llama.cpp) on your GPU cloud instance, pull the model of your choice, and expose it as an OpenAI-compatible API endpoint - with an optional web chat UI.
What you get:
- Ollama / llama.cpp installed and tuned on your GPU instance
- Model of your choice pulled and running
- OpenAI-compatible API endpoint for your apps
- Optional: Open WebUI chat interface
- GPU rental advice if you don't have a server yet (you rent in your own account, I recommend the cheapest option for your model and budget)
What I need from you:
- GPU instance access (SSH login)
- Which model you want to run (or your use case - I'll recommend one)
Python Developer , Web Scraping and Automation Specialist
Languages
Do I need my own GPU server?
Yes - you rent the GPU instance in your own account (RunPod, Vast.ai, etc.). I recommend the cheapest option for your model and budget, then install and configure everything.
Which models can you deploy?
Any model Ollama or llama.cpp supports - Llama, Qwen, Mistral, DeepSeek distills and more. Tell me your use case and I'll recommend one.
Can my apps use the model via API?
Yes - I expose an OpenAI-compatible endpoint, so anything that works with OpenAI's API works with your private model.
