Browse categories
English
$
USD
Connect to your AI
Expert AI and Machine Learning Engineer
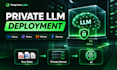
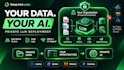
I deploy open-source LLMs privately, inside your own cloud account or on your own servers. Nothing is sent to third-party AI APIs.
I run this stack myself: a 32B Qwen model served with vLLM, behind an OpenAI-compatible API, with API keys, monitoring dashboards (Prometheus and Grafana) and everything packaged in one Docker image.
What you get:
Optional: a RAG chatbot that answers from your own documents and shows its sources.
Good for companies handling private or regulated data (clinics, legal, internal documents).
Message me first with your GPU or cloud and the model you have in mind, and Ill confirm the right setup.
Frameworks:
Scikit-learn
•
DeepPy
•
Google ML Kit
•
PyTorch
Data type:
Code
Programming language:
Python
•
R
•
SQL
•
Amazon SageMaker
Tools:
Jupyter Notebook
•
TensorFlow
•
Amazon SageMaker
•
Colab
Do I need my own GPU or cloud account?
Either works. I can deploy on your own server or on a cloud account you own (AWS, RunPod and similar). Message me first and I’ll advise the GPU size for your model.
Will my data leave my servers?
No. The model runs inside your environment and nothing is sent to third-party AI APIs. I only need access for setup, and you can remove it afterwards.
Which models can you deploy?
Open-source models like Qwen, Llama and Gemma, with quantization. The best choice depends on your GPU memory and your use case.
Can the assistant answer from my own documents?
Yes, that’s the optional RAG add-on. It answers from your files and shows the source. Tell me the document types and volume before ordering.
What do you need from me to start?
Your GPU or cloud details, the model you have in mind (if any), and what apps will call it. I’ll confirm the setup before we begin.


