Browse categories
English
$
USD
Connect to your AI

Your LLM feature passed the demo. Will it still pass after the next prompt or model change?
I build evaluation suites that answer that. You get a rubric written for your use case, a test set with expected answers and, if an LLM grades your outputs, a check of how far that judge can be trusted.
What you get:
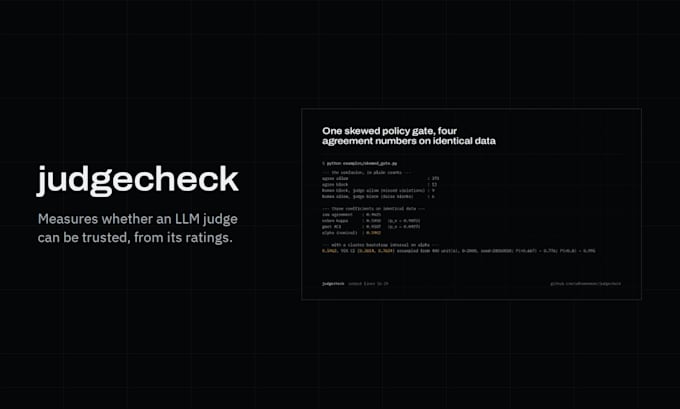
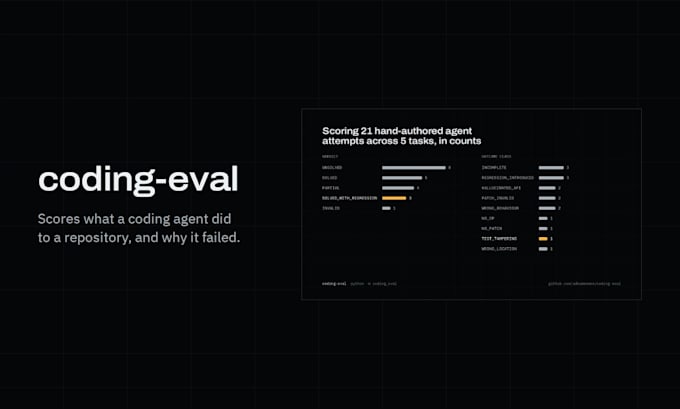
Why me: I built judgecheck, a reliability report for LLM judges that shows how 96% raw agreement can hide chance-corrected scores as low as 0.60, and coding-eval, which replays coding-agent attempts in a sandbox (20 of 21 claimed success; 5 succeeded). I evaluate frontier-model code professionally and build rubric and calibration tooling for Arabic clinical AI.
Message me with what the feature does, a few example inputs and outputs, and what a good answer looks like to you.
AI Red Teaming and LLM Evaluation Engineer
Languages
What do you need from me?
Access to the model or API you use (or a file of saved outputs), a few real example inputs, and any human ratings you already have. If you have none, we agree a small rating round together.