Browse categories
English
$
USD
Connect to your AI
I will build scalable data pipelines using pyspark, databricks, and azure
About this Gig
Struggling with slow SQL queries, messy data silos, or high cloud costs? I am an Enterprise Data Engineer (Microsoft Azure Certified) specializing in PySpark, Azure Databricks, Delta Lake, and SQL. I design, optimize, and build fault-tolerant data architectures that turn raw data into analytics-ready and AI-ready pipelines.
What I Can Do For You:
- ETL / ELT Pipeline Design: Scalable batch & streaming pipelines using PySpark, Databricks, and Azure Data Factory (ADF).
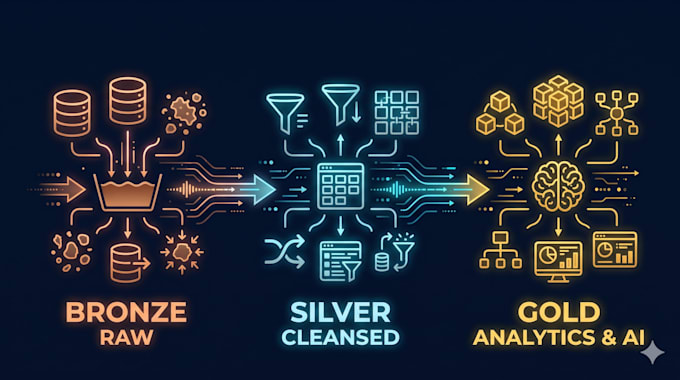
- Medallion Lakehouse Architecture: Structure raw data into Bronze, Silver, and Gold Delta Lake layers on ADLS Gen2.
- Performance & Cost Optimization: Fix slow Spark jobs, resolve data skew, tune Oracle/PostgreSQL queries, and implement Z-Ordering/Liquid Clustering.
- AI & RAG Data Readiness: Connect enterprise data lakes to vector databases (pgvector) and Kubernetes (AKS) for real-time AI retrieval.
Why Work With Me?
- Production-grade, modular code with clear architectural diagrams.
- Deep expertise across Azure, Databricks, Python, and relational databases.
- Clear communication and post-delivery walkthrough.
Message me before ordering so we can align on your data stack and scope!
FAQ
Can you write the actual PySpark / SQL code in addition to the architecture plan?
Yes! Alongside auditing and architecture blueprints, I write production-ready PySpark scripts, Databricks notebooks, and optimized SQL queries. Message me with your requirements for a custom implementation offer.