Browse categories
Explore
Fiverr Pro
English
$
USD
IoT, Ai and Embedded Systems Engineer
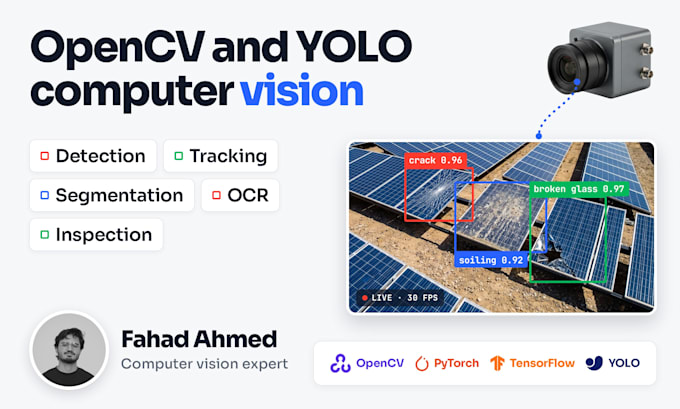
I develop computer vision and deep learning systems with OpenCV, YOLO and PyTorch: from custom trained models to real time video analytics, built to run reliably on your PC, server or edge device.
What I deliver
Technical scope
With formal education in AI and years of engineering experience, I build vision systems that are accurate, fast and easy for your team to run and extend. You receive full source code, trained model weights and documentation.
Contact me before placing an order. I will review your project and timeline and send you an accurate quote.


APIs:
Microsoft Computer Vision AI
•
Google Cloud Vision API
Programming language:
Python
•
Colab
•
Other
Tools:
Jupyter Notebook
•
OpenCV
•
TensorFlow
•
Colab
•
PyTorch
•
Other
Frameworks:
Scikit-learn
•
Keras
•
PyTorch
•
Other
Which computer vision tasks do you handle?
Detection, classification, segmentation, tracking, pose estimation, OCR, visual inspection, measurement, calibration and stereo vision. If your task is different, describe it and I will tell you the right approach.
Do I always need deep learning?
No. Many tasks are faster and more reliable with classic OpenCV image processing. I choose between OpenCV and deep learning based on your accuracy, speed and hardware.
Can you train a model on my own data?
Yes. I annotate your images, train a custom model and report precision, recall and mAP on a test set you can check.
How accurate will it be?
It depends on your images and conditions. I test on your real data and tell you honestly what accuracy to expect before we start.
Can it run in real time?
Yes. I optimise with ONNX, TensorRT or OpenVINO and choose the right model size for your hardware and frame rate.
Do you sign NDAs?
Yes. I'm happy to sign an NDA before discussing confidential projects.
Can it work with my cameras?
Yes. I read IP cameras over RTSP, USB cameras and video files, and can process several streams at once.
Can it run on a Raspberry Pi or Jetson?
Yes. I deploy on PC, cloud servers, Raspberry Pi and NVIDIA Jetson, and optimise the pipeline for each.
What do you need from me to start?
What you want the system to see or measure, sample images or video, and where it should run. A short description is enough to start.
Do I get the source code and model?
Yes. You receive full source code, trained model weights and documentation. You own all of it.