Browse categories
Explore
Fiverr Pro
English
$
USD
AI Data Engineer, RAG Pipelines, PDF to Markdown, Local LLMs
Protect your proprietary company data with a 100% private, locally fine-tuned AI.
Sending sensitive business documents, instructional material, or internal knowledge to public cloud APIs is a major security risk and frequently violates GDPR regulations.
I build secure, offline AI models tailored to your specific industry domain. By leveraging high-end Apple Silicon architecture (128 GB Unified Memory) and advanced frameworks like MLX and Unsloth, your data never leaves my isolated, local hardware during the training process.
What I Deliver:
My Tech Stack & Expertise:
Please message me before placing


Programming Language:
Python
Data Type:
Text
AI Engine:
Other
Why should I fine-tune locally instead of using OpenAI or other cloud APIs?
Cloud APIs pose a major security risk for proprietary company data and frequently violate strict GDPR policies. Local fine-tuning guarantees that your sensitive documents, client data, and internal knowledge never leave an isolated, offline environment. You retain 100% data sovereignty.
Are you able to fine-tune larger models on local hardware?
Yes. I leverage a high-end Apple Silicon architecture with 128 GB Unified Memory. Combined with advanced quantization frameworks like MLX and Unsloth (QLoRA), this massive memory bandwidth allows me to efficiently fine-tune and run large open-source models (like Llama, Mistral, or Qwen) completely o
What format should my training data be in?
For the Standard package, your data should be prepared as a clean JSONL file containing structured instruction-response pairs. If your knowledge is currently trapped in messy PDFs, raw text, or internal documents, my Premium package includes custom Python preprocessing to extract, clean, and format
What exact files will I receive upon delivery?
You will receive the fine-tuned LoRA adapter weights along with a fully merged and quantized model file (GGUF format). This GGUF file is deployment-ready and can be instantly drag-and-dropped into local inference engines like Ollama, LM Studio, or AnythingLLM on your own company hardware.
How do you ensure the model actually learns my domain and doesn't just overfit?
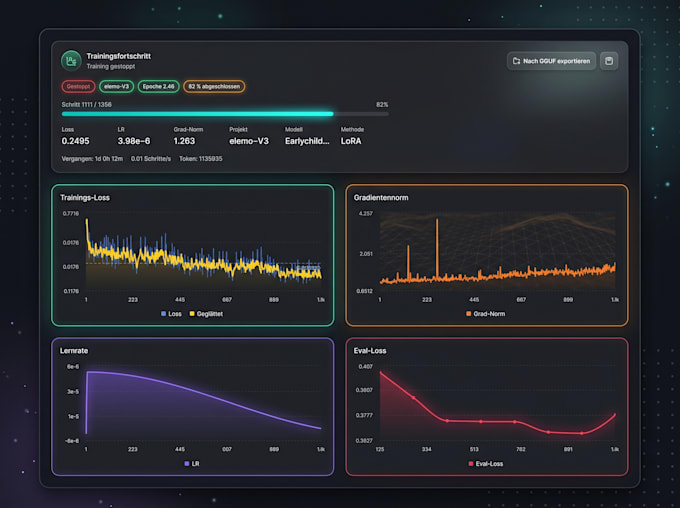
I rigorously monitor training loss curves and adjust hyperparameters to ensure the model generalizes well to your specific terminology.