Browse categories
Explore
Fiverr Pro
English
$
USD
Machine Learning Engineer, AI Agents, MCP and Computer Vision
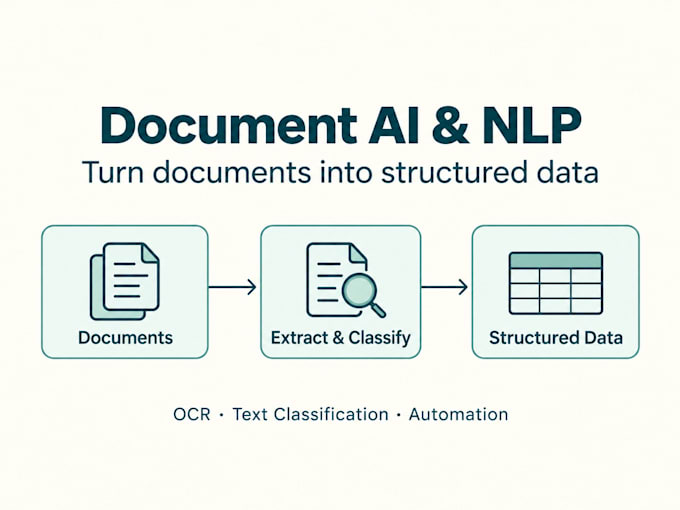
I build NLP and document processing pipelines for text classification, structured extraction and workflow automation.
Depending on your task, I prepare and label data, fine-tune a transformer model or use an LLM extraction pipeline, validate fields, and deliver Python code or a FastAPI service.
My procurement work includes eligibility classification with Macro F1 0.9639 and 96.4% accuracy, and document extraction pipelines processing approximately 2,000 notices per day. These are results from specific projects, not guarantees for new data.
The scope can include PDF, HWP/HWPX or text processing, JSON or CSV outputs, field validation, evaluation and deployment instructions. OCR and unusual layouts should be discussed before ordering.
Please send representative files, required fields or labels, data volume and your target environment. We will agree on deliverables and acceptance criteria before work begins.

What relevant NLP experience do you have?
I built procurement eligibility classifiers using RoBERTa and LoRA, document extraction pipelines, and INT8 ONNX models served through FastAPI. My work covers data preparation, evaluation and deployment, with results measured separately for each task.
What if I have very little labeled data?
We can consider transfer learning, weak supervision or an LLM baseline, depending on the task. I will inspect representative examples and evaluate on held-out data. A small sample alone does not guarantee reliable accuracy.
Can you handle data collection too?
Data preparation or collection can be included when sources, authorized access and required fields are agreed in advance. Document formats and OCR needs must be reviewed using sample files before I confirm scope.
How accurate can the models be?
Accuracy depends on the task, labels, data quality and evaluation split. We establish a baseline and measure on held-out samples using appropriate metrics such as precision, recall and F1. Past project results are not guarantees for a new dataset.
