Browse categories
English
$
USD
Connect to your AI

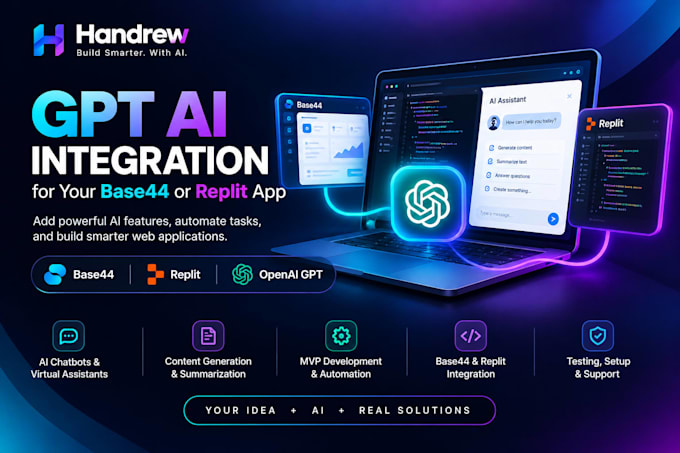
I will integrate GPT into your Base44 or Replit project and deliver a working prototype (chat, webhook automation, optional memory) that turns your idea into a demonstrable, secure AI feature ready for demos or further productionization.
What I can build
What you'll get
Why work with me?
ORDER NOW
AI App Development , GPT Integration Specialist
Languages
Do you need my OpenAI API key?
I can use your key or help create one keys stay in environment variables (e.g., OPENAI_API_KEY) and are never committed or exposed client-side.
Can you deliver the prototype in 48 hours?
Yes — for small-scope projects (one chat page + one webhook) with immediate access and clear requirements.
How do you secure webhooks and requests?
I implement HMAC/secret-token verification, payload validation, rate limiting, and retry/backoff for reliable delivery.
How do you control OpenAI costs?
I use token caps, request summarization, caching, and basic usage logging so spend is predictable and limited.
Will conversation memory be stored and is it private?
Short-term per-session memory is included as an option; long-term vector memory is an add-on — storage and retention remain under your control.
