Browse categories
Explore
Fiverr Pro
English
$
USD
Copy-pasting from PDFs doesn't scale, and generic OCR mangles tables. Cheap data-entry gigs work until you need it repeatable, auditable and running every week without you.
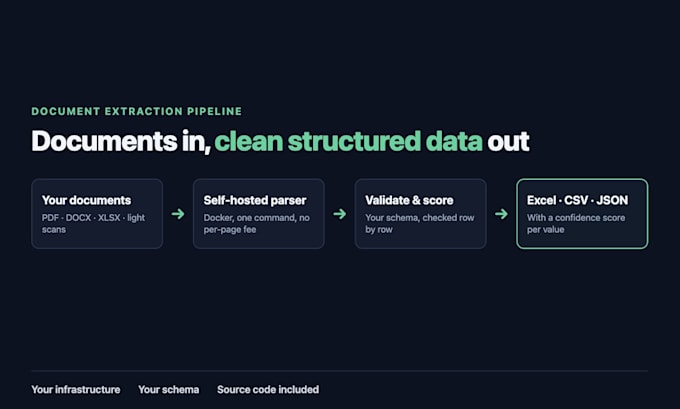
I build the pipeline instead: documents in, clean structured data out, on your own infrastructure.
WHAT YOU GET
- A pipeline you run yourself (Docker, one command)
- Your schema, your fields, validated on every row
- Confidence scoring on every extracted value
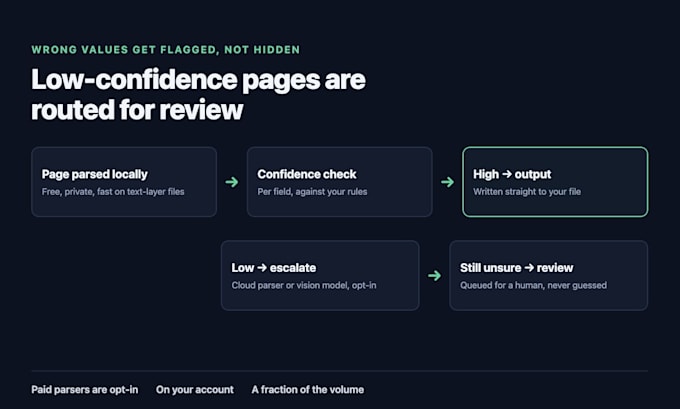
- Low-confidence pages routed for review, not silently wrong
- Excel, CSV or JSON output
- Source code and setup docs
WHY SELF-HOSTED
The parser runs locally: no per-page fee, and your documents never leave your infrastructure. Paid cloud parsers are used only for pages that genuinely need them - a fraction of the volume, on your account, at your discretion.
HOW I WORK
Start with the Pilot. Send 20-50 real pages. I run them through and send a written report: what extracted cleanly, what didn't, and which fields need review rules. Then you decide.
IN SCOPE
Text-layer PDF, DOCX, XLSX, PPTX and light scans. Handwriting, forms and charts are quoted separately - just ask.
Send 3-5 sample pages and the fields you need.
Technology:
Excel
•
Python
How is this different from a $20 data-entry gig?
A data-entry gig types your documents once. This is a pipeline you own and re-run forever, with validation rules and confidence scores so you can see which values to trust. A different purchase entirely.
Do I pay per page?
Not to the parser - it runs on your own machine, so page volume is free. Only pages that need a cloud parser or vision model cost anything, on your own account, and you decide whether to enable that at all.
What accuracy can you promise?
None before I've seen your documents, and be sceptical of anyone who does. Published parser benchmarks disagree wildly and results depend on your specific layouts. The Pilot measures it on your real pages first.
Do my documents leave my infrastructure?
Not by default. The parser is self-hosted. Cloud parsers are opt-in, per-page, and only for pages the local pipeline flags as low confidence. If you need zero external calls, say so and I'll build it that way.
Can you handle scanned documents?
Light scans, yes. Heavy scans, handwriting and forms are possible but need a separate quote. They are genuinely harder, and I'd rather price them honestly than under-deliver.
What happens to values it gets wrong?
They're flagged, not hidden. Every value carries a confidence score, and low-confidence rows are routed out for review rather than silently written into your spreadsheet.
Who runs it after handover?
You do. It's a Docker container plus your code, with setup docs. One command to start.