Browse categories
Explore
Fiverr Pro
English
$
USD
Data Engineer
Are you facing slow queries in BigQuery, broken dbt models, or unoptimized Spark jobs?
I am a Senior Data Engineer (Databricks Associate Certified) with 5+ years of experience building and optimizing scalable cloud data architectures (GCP, Databricks, BigQuery). I specialize in turning complex, slow, and expensive data pipelines into fast, efficient, and cost-effective workflows.
What I can do for you:
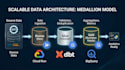
- dbt & Data Warehousing: Build and refactor dbt models following Medallion Architecture (Bronze, Silver, Gold), optimize SQL queries, and set up Cloud Run / Control-M / Airflow executions.
- PySpark & Databricks: Debug, refactor, and speed up batch ETL pipelines with Spark (Scala/Python).
- GCP Cloud Architecture: Set up scalable pipelines with BigQuery, Cloud Run, and Airflow/Composer.
- Database & Query Optimization: Reduce BigQuery/Snowflake processing costs and execution times.
Why work with me?
- Certified Expertise: Databricks Certified Data Engineer & Azure Certified.
- High-Quality Code: Clean, modular, and maintainable data engineering practices.
- Clear & Direct Communication: English and Spanish available.
NOTE: Contact me with your requirements before placing

Tools & Platforms:
Google Cloud Dataflow
•
Apache NiFi
•
Other
Do you accept custom, long-term orders?
Yes, but only for scoped micro-tasks or part-time consulting. Please send me a message first to discuss details.
What do I need to provide before starting?
Access to the cloud environment (or anonymized sample data/codebase) and a clear description of the expected output/error logs.
Can we schedule a call to discuss the project?
Yes, via Fiverr's video call feature once an order or request is initialized.


