Browse categories
Explore
Fiverr Pro
English
$
USD

AI Backend Engineer | RAG Pipelines · LLM Integration · Agentic Systems
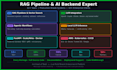
I'm a Senior Software Engineer with 12+ years building production AI systems. I'm the sole architect of Teqit a live enterprise platform with RAG pipelines, on-premise LLM inference, and agentic microservices serving 10+ clients.
What I build for you:
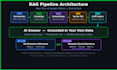
- RAG pipelines document ingestion, vector search, LLM answer generation
- LLM API integration OpenAI, Claude, Gemini, or any hosted model
- Local LLM inference with Ollama / llama.cpp (cut AI costs ~70%)
- Agentic workflows tool calling, multi-step reasoning, decision pipelines
- FastAPI or Scala backends via REST or gRPC
- Hybrid routing smart switching between local and cloud models
Why me?
I've done this in real production not tutorials. I've cut AI costs 70% with local inference, built generative video avatar pipelines, and designed agents that independently reason over enterprise knowledge bases.
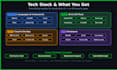
Tech: Python · FastAPI · Ollama · OpenAI API · Akka/Scala · Docker · AWS
Message me before ordering I'll review your use case first.
Senior AI and Backend Engineer
Languages
Can you use my own documents as the knowledge base?
Yes — PDFs, Word docs, text files, or databases. I handle the full ingestion and chunking pipeline.
Can I host this on my own server or AWS?
Absolutely. I set up Docker + AWS EC2 deployments and can configure for any cloud provider.
Do I need an OpenAI API key?
Only if you want cloud models. For local inference using Ollama, no external API key is needed.
Will you share the source code?
Yes — full source code with documentation is delivered for all packages.
Can you integrate this into my existing app?
Yes, as long as you share API specs or codebase access. Message me first to discuss your setup.


