Browse categories
Explore
Fiverr Pro
English
$
USD
Senior Data Engineering and Analytics Expert
Do you need a scalable ETL/ELT pipeline or Medallion Lakehouse solution in Azure Databricks?
I will build and optimize Azure Databricks data pipelines using PySpark, Spark SQL, Delta Lake, and modern data-engineering practices.
I can help with:
Azure Databricks ETL/ELT pipelines
PySpark and Spark SQL transformations
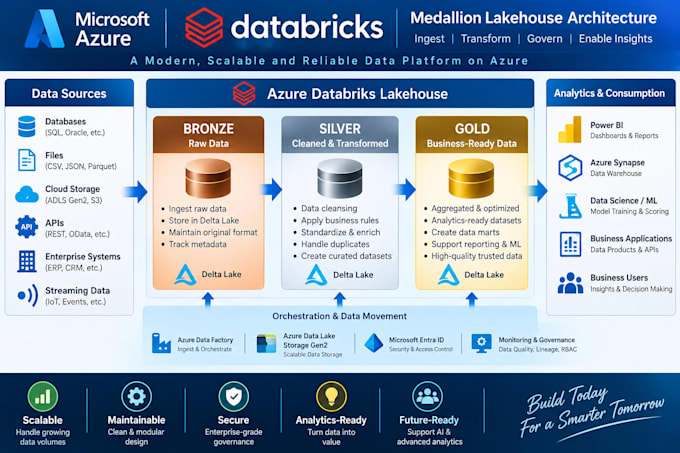
Bronze, Silver, and Gold Medallion architecture
Delta Lake tables and data processing
ADLS Gen2 data integration
Data cleansing, transformation, and aggregation
Data quality checks and validation
Pipeline troubleshooting and optimization
ADF-oriented orchestration design
Documentation and implementation guidance
My approach
I focus on building maintainable, scalable, and well-structured data solutions rather than simply writing code. I review your data sources, business rules, transformations, expected outputs, and technical requirements before designing the solution.
Before ordering: Please contact me for complex or production workloads and share your data sources, expected outputs, target architecture, transformation requirements, and Azure environment details.

Expertise:
Automation
•
Other
Cloud provider:
Microsoft Azure
FAQ 1 — What types of Azure Databricks projects can you help with?
I can help with ETL/ELT pipelines, PySpark and Spark SQL transformations, Delta Lake processing, Medallion Bronze-Silver-Gold architecture, data quality, validation, troubleshooting, and performance optimization.
FAQ 2 — Can you build Bronze, Silver, and Gold Medallion pipelines?
Yes. I can design and build Medallion pipelines where Bronze stores raw data, Silver applies cleansing and transformations, and Gold prepares business-ready datasets for analytics and reporting.
FAQ 3 — Which technologies can you work with for this service?
Depending on the project, I can work with Azure Databricks, PySpark, Spark SQL, Delta Lake, ADLS Gen2, Azure Data Factory, SQL, and Python.
FAQ 4 — Can you integrate Azure Data Factory with Databricks?
Yes. I can support ADF-oriented orchestration designs for ingesting data, triggering Databricks processing, managing dependencies, and supporting end-to-end ETL/ELT workflows.
FAQ 5 — Can you optimize an existing PySpark or Databricks pipeline?
Yes. I can review transformations, joins, partitioning, caching, shuffle behavior, Delta-table design, and other relevant areas to identify appropriate performance improvements.
FAQ 6 — Do you need access to my Azure or Databricks environment?
Not always. Code, representative data, architecture details, requirements, and expected outputs may be sufficient for some projects. Environment access can be discussed when implementation or testing requires it.
FAQ 7 — Can you work on large or production Databricks projects?
Yes, but please contact me before ordering. Projects involving multiple data sources, complex transformations, production deployment, security requirements, orchestration, or large workloads may require a custom scope and offer.