Browse categories
Explore
Fiverr Pro
English
$
USD
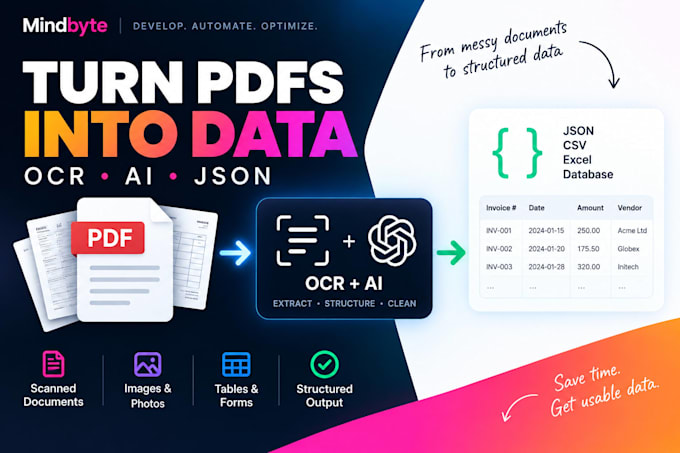
I build OCR and document-processing pipelines that turn PDFs, scans and images into structured, usable data.
I can extract text, tables, dates, references, IDs and custom fields, classify documents, clean the results and return structured JSON, CSV or database-ready output.
Depending on the project, I can also build APIs, asynchronous processing, semantic search or RAG workflows.
My focus is on reliable, reusable document processing rather than simple one-off PDF conversion.
Please send representative sample documents before ordering complex projects.
Technology:
Python
Can you process scanned PDFs?
Yes. I can process scanned PDFs and images, including preprocessing when needed.
Can you extract specific fields?
Yes. Dates, IDs, references, titles, document types, and other fields can be extracted.
Can you classify documents?
Yes. Classification can use rules, machine learning, or AI depending on the use case.
Can you extract tables?
Yes, depending on document layout and scan quality.
Can you build an API around the pipeline?
Yes. REST API and background processing can be added.
Can you process large volumes?
Yes, but high-volume workflows usually require a custom scope.
