Browse categories
English
$
USD
Connect to your AI

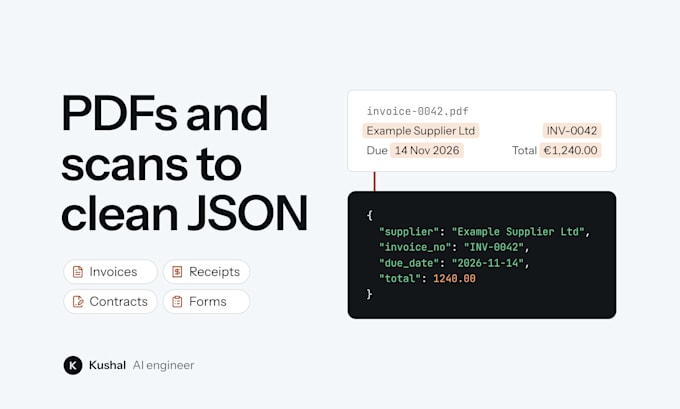
Tired of copying data out of PDFs by hand? I build AI pipelines that read invoices, receipts, contracts, forms, reports and scanned documents and turn them into clean, structured data.
In my current role I built document pipelines with vision-model OCR, grounded extraction that checks each value against the source text, and validation before anything reaches the database.
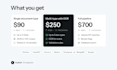
WHAT YOU GET
- Extraction of the fields you need into Excel, CSV, JSON or your database
- Support for digital PDFs AND scanned or photographed pages
- Validation rules, with uncertain values flagged for review
- A script or API you can run on new documents yourself
GOOD FOR
- Invoices, receipts and purchase orders
- Contracts and legal documents (parties, dates, amounts, clauses)
- Forms, applications and reports
- Bank statements and financial documents
HOW IT WORKS
1. You share 10-20 sample documents and the fields you need
2. I build and test the extraction on your samples, then share accuracy
3. You get the code, the results and a guide to run it on new files
There's a sample extraction report in the gallery.
Send me a sample document first and I'll tell you what's possible.
AI Engineer: RAG chatbots, LLM apps and PDF extraction
Languages
How accurate is it?
It depends on document quality. You get an accuracy report on your own samples before the final delivery, and uncertain values are flagged rather than guessed.
Can it handle handwriting or poor scans?
Printed text and clean scans work well. Handwriting and low-quality photos vary, so send a sample and I'll check first.
How many documents can it process?
The scripts handle batches of thousands. Premium adds a queue for continuous processing.
Is my data safe?
I use it only for your project and delete my copy after delivery. Redacted samples are fine for testing.
What does it cost to run afterwards?
Usually fractions of a cent to a few cents per page, depending on the model. I'll estimate it for your documents.
Which tools do you use?
Python, with LlamaParse for digital PDFs and a vision model (GPT or Claude) for scans and photos. Every value is checked against the source text before it's saved.
Can I see an example first?
Yes. There's a sample extraction report in the gallery, and you can send me one of your own documents before you order.