Browse categories
Explore
Fiverr Pro
English
$
USD
Transforming Data into Solutions with Precision
Need a data engineer for your ETL pipelines? Airflow DAG failing? Spark job running out of memory? I fix broken data pipelines fast, then make sure they don't break again.
Tired of 2 AM DAG failures? I add an AI agent to your Airflow + Spark stack that diagnoses failures, fixes the safe ones automatically, and sends you a clear root-cause report for the rest.
What you get:
The Tech Stack: Airflow, Spark, Kafka, NiFi, HDFS, MinIO, Agentic Frameworks.

Destination Platform:
PostgreSQL
•
MySQL
•
Apache Hive
•
Amazon S3
•
Other
How is Agentic ETL different from traditional ETL?
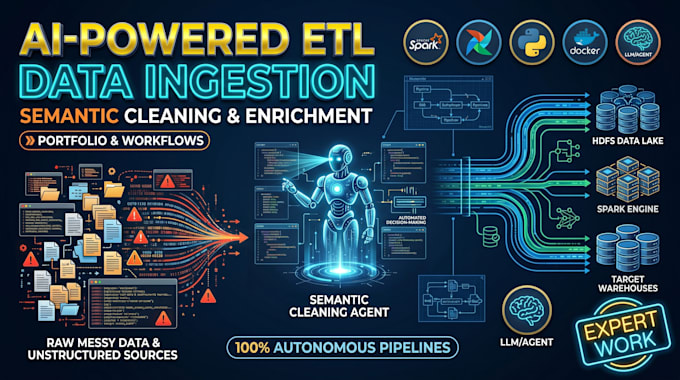
Traditional ETL relies on rigid, hardcoded rules that break when data formats change. My Agentic ETL pipelines use AI to semantically understand, parse, and clean unstructured or messy data before feeding it securely into your HDFS data lake, making the pipeline highly resilient.
Is my enterprise data secure when using these AI agents?
While we can integrate commercial APIs, I specialize in deploying secure, local LLMs (such as Qwen, DeepSeek, framework-based agents) directly within your containerized environment. This ensures your sensitive data never leaves your internal network or cluster.
Do I need to migrate off my current infrastructure?
No. I engineer these agentic workflows to integrate seamlessly with your existing Apache Airflow and Spark setups. I package everything using Docker (or Docker Swarm for high availability) so it bolts directly onto your current architecture.
What if the agent can’t fix a failure?
It escalates. You get a Slack or email alert with the root cause, the relevant log lines, and a suggested fix. Risky changes (code, schema, anything touching production data) always need your approval. The agent only auto-fixes failure types we’ve agreed are safe.
Can you build a new ETL pipeline from scratch, not just fix one?
Yes. I design and build end-to-end data pipelines: ingestion from APIs, databases or files, transformation in PySpark or Python, orchestration in Apache Airflow, and loading into PostgreSQL, S3, Hive or your data warehouse.