Browse categories
Explore
Fiverr Pro
English
$
USD

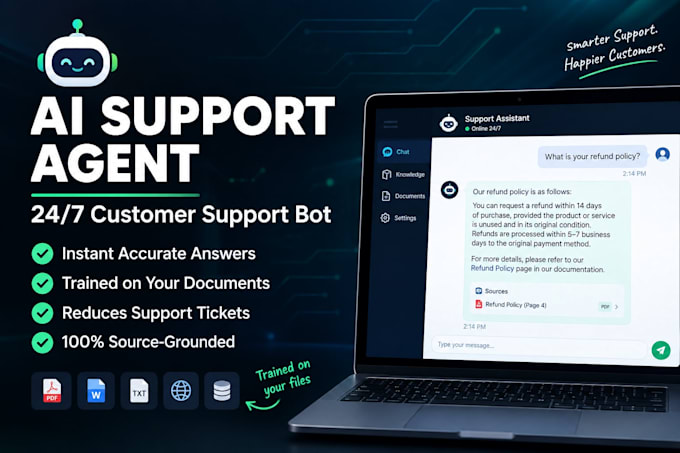
Production-Grade RAG PDF Research Agent
Get high-performance Retrieval-Augmented Generation (RAG) systems tailored to your documents. No hallucinations.
️ TECH: Python Streamlit ChromaDB BM25 Groq LLaMA LangChain Docker
CHOOSE YOUR TIER:
BASIC ($90) Starter RAG Agent
Ideal for simple proof-of-concept tasks.
Semantic Vector Search (Single PDF)
Streamlit UI Chatbot Frontend
Clean, modular source code
STANDARD ($180) Hybrid RAG Agent
Highly recommended for accurate business data.
Hybrid Search (BM25 Keyword + Semantic)
Smart Router (Falls back to Web if PDF lacks data)
Eval script with accuracy proof
PREMIUM ($450) Production RAG System
Enterprise-ready pipeline built for scale.
All Standard features + Advanced Reranking
Multi-PDF processing & parsing
Docker containerized for instant cloud deployment
EVERY ORDER INCLUDES:
- Comprehensive README instructions
- Clean, thoroughly commented code
- Post-delivery support
PERFECT FOR: Startups, researchers, and developers who need elite AI Q&A without expensive APIs.
Message before ordering to discuss your custom architecture!
Building Autonomous AI Agents Advanced RAG Systems
Languages
Q: What do I need to provide to start?
Simply send me your PDF(s), project requirements, and any specific features you want. If you have a preferred AI model, API, or UI design, let me know before we begin.
Q: What is the difference between Semantic and Hybrid Search?
Semantic search (Basic) finds context and meaning. Hybrid search (Standard/Premium) combines this meaning with BM25 keyword matching, ensuring specific terms, numbers, or section IDs are never missed.
Do you provide hosting or cloud deployment?
I provide a fully Containerized Docker setup (Premium) or clear local deployment instructions. Cloud hosting costs and server setups are managed by the buyer, though I assist in configuration.
What is the purpose of the evaluation script?
It tests the RAG pipeline against factual questions to generate an accuracy score, proving the system effectively retrieves true data without hallucinating before you deploy it.
Can I use this architecture with open-source LLMs?
Yes! The setup is modular. We can plug in commercial APIs (OpenAI/Anthropic) or free, high-speed open-source models via Groq (LLaMA 3.1/3.3), Ollama, or Hugging Face.
