Browse categories
English
$
USD
Connect to your AI
AI Engineer: LLM Agents, RAG, Document AI : Computer Vision and Video Analytics
Level 1
Has met certain performance criteria and shows strong potential in the marketplace.
Still paying someone to type data off invoices, receipts or forms by hand?
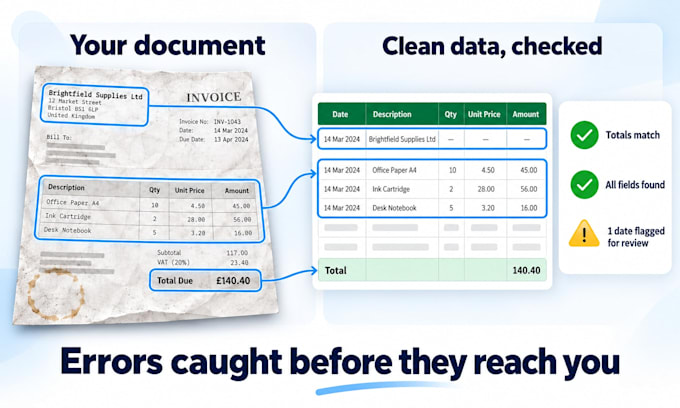
I build AI OCR systems that read your documents and return clean, structured data straight into Excel, Google Sheets, your database or your app.
WHAT I EXTRACT
- Invoices and receipts: line items, totals, dates, tax, supplier details
- Bank statements, purchase orders and delivery notes
- ID and KYC documents: passports, licences, national IDs
- Contracts and forms: fields, signatures, checkboxes
- Handwritten and poor quality scanned pages
- Tables, even when they run across multiple pages
WHY IT IS DIFFERENT
Every job includes validation rules that catch errors before they reach you: totals that don't add up, missing fields, impossible dates. You also get an accuracy report measured on YOUR documents, not a demo.
STACK: Python, PaddleOCR, Tesseract, AWS Textract, Google Document AI, Azure Document Intelligence, vision LLMs.
NOT SURE IT WILL WORK ON YOUR DOCUMENTS?
Message me 2 or 3 samples and the fields you need before ordering. I will tell you honestly what accuracy to expect.

Technology:
Excel
•
Google Sheets
•
Python
•
Zapier
•
Other
Will this work on my specific documents?
That is exactly what the Proof of Concept package is for. Send 3-5 of your real documents and I will run extraction on them and show you the results with an accuracy report before you commit to anything larger. If your documents turn out to be a poor fit, you will find out for a small amount rather
What accuracy can I expect?
It depends on your documents, and anyone who quotes you a number before seeing them is guessing. Clean digital PDFs with consistent layouts typically reach very high accuracy. Poor scans, handwriting and highly variable layouts are harder. This is why every package includes an accuracy report measur
Do I get the source code and a working API?
Yes, from the Standard package up. You get full source code, and Premium includes an API plus deployment to your own server, containerised with Docker, and documentation so your team can maintain it without me.
My documents are confidential. Is my data safe?
Yes, and I will be specific about it. I only need sample documents, and you can redact sensitive values before sending. If your documents cannot be processed by a third-party service at all, I can build the whole pipeline with self-hosted open-source OCR so nothing leaves your own infrastructure. Te
Can you handle handwritten text or low-quality scans?
Often yes, but honestly it varies more than printed text does. Handwriting, faded scans, skewed photos and low-resolution faxes all reduce accuracy, and the extent depends on your specific documents. Pre-processing helps a lot. Send samples of your worst-case documents in the Proof of Concept and yo
What output format do I get?
Whatever fits your workflow: structured JSON, CSV, Excel, or written directly into your database or app via API. Tell me where the data needs to end up and I will deliver it in that shape rather than handing you a file to convert yourself.
I just need my PDFs converted once, not a whole system. Can you do that?
Yes. The Basic package is exactly that: send up to 50 pages of one document type and I return a clean Excel, CSV or JSON file. If you later want it automated, the Standard package turns the same setup into a reusable pipeline.