Browse categories
English
$
USD
Connect to your AI
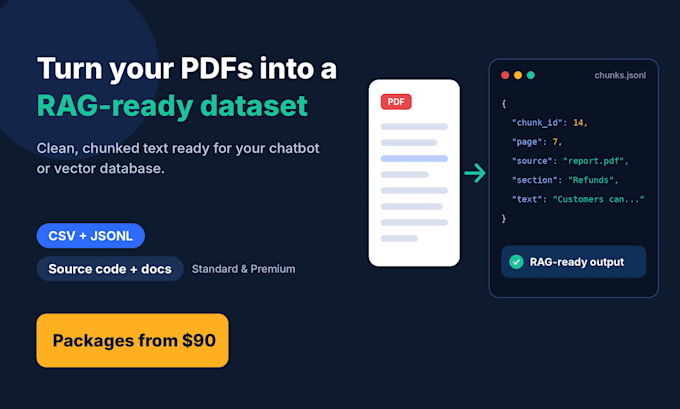
Need your PDFs turned into a clean, RAG-ready dataset? I build structured data you can plug straight into your RAG pipeline, chatbot, or knowledge base.
What you get:
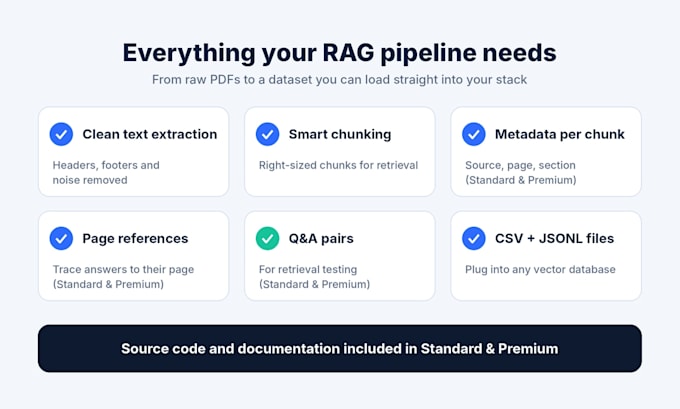
️ Accurate text extraction (headers, footers and noise cleaned)
️ Smart chunking with page references
️ Metadata for every chunk (source, page, section)
️ Ready-made Q&A pairs for retrieval testing and LLM evaluation (Standard & Premium)
️ JSONL dataset + CSV, ready for your RAG pipeline and vector database
️ Source code and documentation (Standard & Premium)
How I work: I cross-check outputs across multiple models and manually verify samples against your source text to reduce hallucinations. I handle your files confidentially.
Perfect for: AI startups, chatbot builders, researchers and developers building a knowledge base or RAG pipeline.
Start with Basic to test one PDF, then scale up. Message me before ordering with your PDF type and page count!

Expertise:
Other
Frameworks:
Panda
Data type:
Text
Programming language:
Python
•
SQL
Tools:
Excel
•
Colab
APIs:
OpenAI
What files do you accept?
PDFs only. If your file is Word, PPT or an image, message me first so I can confirm if it can be converted.
Do you work with scanned PDFs?
Text-based PDFs work best. Scanned PDFs need OCR and may need extra time or a custom offer, so please send a sample page before ordering.
What will I receive?
Every package gives you a clean CSV + JSONL dataset with chunked text. Standard & Premium also include metadata, page references, Q&A pairs, source code and documentation.
Are my files confidential?
Yes. I don't share or reuse your files for anyone else. If your documents are sensitive, tell me before ordering so I can confirm how they will be handled.
How many pages are included?
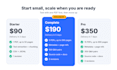
Basic: 1 PDF up to 50 pages. Standard: 5 PDFs up to 200 pages. Premium: 15 PDFs up to 600 pages. For more, message me for a custom offer.
Can I test with one PDF first?
Yes, that's exactly what Basic is for. Test one PDF, check the quality, then scale up to Standard or Premium.