Browse categories
Explore
Fiverr Pro
English
$
USD
Scalable SaaS and Web Apps, Senior MERN, Rails and DevOps Engineer
Are your API integrations failing, ETL jobs skipping records, or dashboards showing incomplete data?
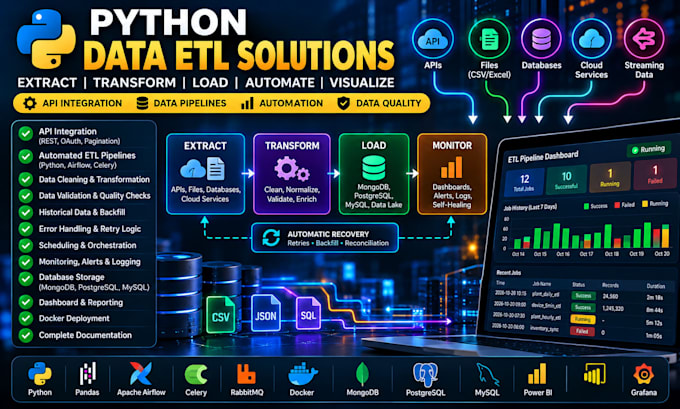
I build and repair reliable Python ETL/ELT pipelines that move data from REST APIs, databases, CSV/Excel and cloud storage into clean, usable datasets.
What I can deliver:
API integration, pagination, OAuth and rate-limit handling
Automated ETL/ELT with Python, SQL, Pandas or Polars
Incremental sync, checkpoints, deduplication and safe upserts
Data validation, quality checks and data reconciliation
Historical data backfill, retries and failed-job recovery
Scheduling and task queues using cron, Celery/RabbitMQ or Airflow
Structured logs, failure alerts and pipeline monitoring dashboards
PostgreSQL, MySQL, MongoDB, BigQuery or Snowflake integration
Docker deployment, Pytest tests and clear documentation
Ideal for SaaS, e-commerce, IoT, finance and reporting pipelines.
I focus on recoverable, observable workflowsnot one-time scripts. Backfill depends on source API history and access limits.
Message me with your source, destination and current issue before ordering.


Tools & Platforms:
Kafka Connect
•
Other
Can you fix an existing ETL pipeline?
Yes. I can review existing Python ETL scripts, investigate failed API requests, identify data-processing errors, improve database operations, and implement appropriate retry and recovery mechanisms.
Can you recover missing historical data?
Yes, provided the source API or database makes the historical records available. I can implement automated backfill workflows that identify missing periods, retrieve available records, and safely update your database.
Do you provide automatic retries and failure recovery?
Yes. Depending on your requirements, I can implement retry logic, exponential backoff, persistent job tracking, recovery queues, and task execution using Celery and RabbitMQ.
Which databases do you support?
I can work with databases such as PostgreSQL, MongoDB, and MySQL. Cloud warehouse integrations, including BigQuery and Snowflake, can also be discussed based on your project requirements.
Can I monitor my data pipelines?
Yes. I can implement execution logs, job status tracking, failure alerts, daily health reports, and custom monitoring interfaces using Python-based backend technologies.
Can you guarantee that no data will ever be lost?
No system can guarantee the availability of data held by external providers. However, I can implement reliable execution tracking, validation, retries, reconciliation, and recovery mechanisms to reduce preventable data loss and detect unresolved gaps.