Browse categories
Explore
Fiverr Pro
English
$
USD
Enterprise data engineer building automated pipelines and optimizing SQL
Need help processing large datasets with PySpark or Databricks?
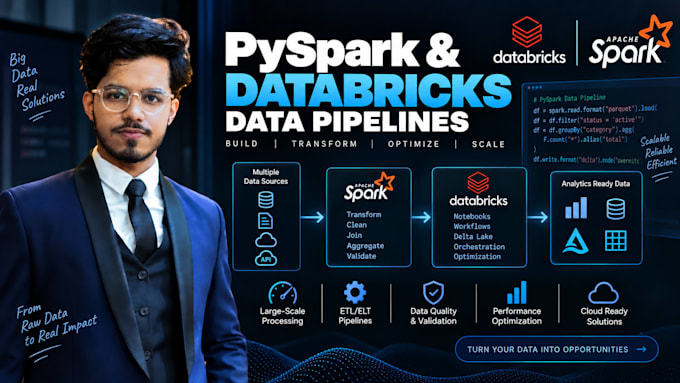
I will build scalable data pipelines using PySpark, Apache Spark, and Databricks for data transformation, processing, and analytics.
I can help with:
I focus on clean, maintainable, and efficient pipelines with clear documentation.
Contact me before ordering for complex projects so I can understand your data and requirements.
Warehouse Platform:
Snowflake
•
Azure Synapse
•
Databricks
Project Type:
New Build
Do you work with Databricks?
Yes. I can build PySpark notebooks, transformations, ETL workflows, and data-processing pipelines in Databricks.
Can you process large datasets?
Yes. PySpark is designed for distributed processing, and I can build pipelines for large datasets.
Can you optimize an existing Spark pipeline?
Yes. I can investigate slow jobs and optimize transformations, joins, partitions, and Spark workloads.
Can you build incremental pipelines?
Yes. I can implement incremental/batch processing based on your requirements and available data.
What data sources can you use?
I can work with files, APIs, databases, cloud storage, and data warehouses depending on the project.
Can you work with Snowflake or other warehouses?
Yes. I can build pipelines that transform data and load it into platforms such as Snowflake and other supported warehouses.
Do you provide documentation?
Yes. Documentation is included according to the selected package.
Should I contact you before ordering?
Yes, especially for complex projects. Please share your data sources, expected transformations, destination, and approximate data volume.
