Browse categories
English
$
USD
Connect to your AI
Looking for an experienced Databricks data engineer to build a reliable, scalable data pipeline? I'm a Databricks Certified Data Engineer with 5+ years of experience building large-scale ETL pipelines using PySpark, Spark SQL and Delta Lake for global clients in finance and healthcare.
What I deliver:
Why work with me:
Have more than 3 sources or custom requirering and I'll send a custom offer.
Which cloud platform do you support?
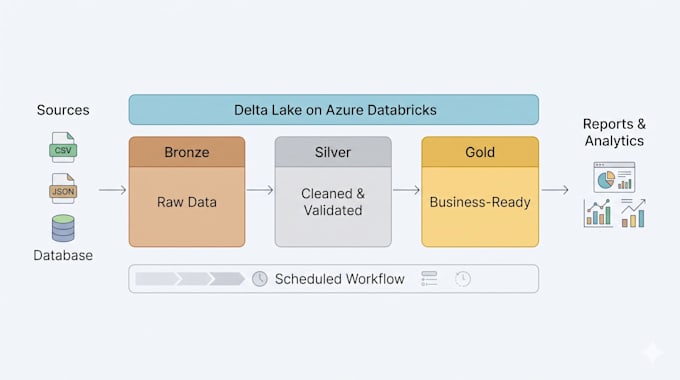
I specialize in Azure Databricks, including ADLS Gen2 storage and Azure Data Factory.
What if I have more than 3 data sources?
Message me before ordering with your requirements, and I'll send a custom offer.
What will I receive at the end?
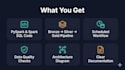
PySpark/Spark SQL notebooks, a scheduled Databricks Workflow, an architecture diagram, and documentation explaining how to run and maintain the pipeline.
Can you work with my existing data format?
Yes. I can ingest CSV, JSON, Parquet, Delta and database tables. Share a sample before ordering if your format is unusual.