Browse categories
English
$
USD
Connect to your AI
AI Engineer, LLM Chatbot and Python Django Expert
Python Web Scraping | Data Extraction | Web Automation
Need reliable data extraction without missing fields, broken scripts, or IP bans? I build high-performance Python web scrapers and automation workflows that pull structured data from even complex static and dynamic websites handling anti-bot measures, proxies, and rate limits along the way.
What I Can Scrape & Extract:
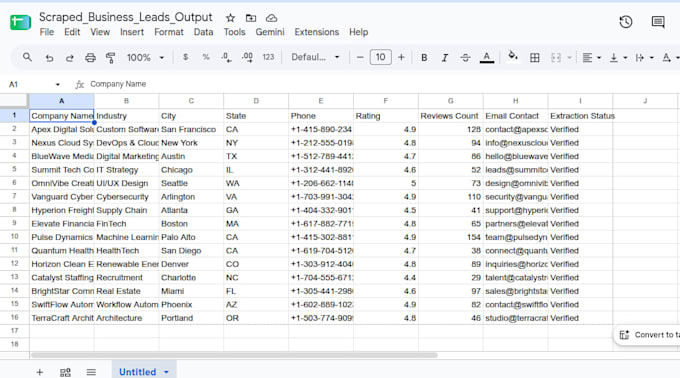
Deliverables:
Tech Stack: Python, Selenium, Scrapy, BeautifulSoup, Playwright, Pandas
Message me with your target website URL and the data fields you need I'll confirm feasibility and give you an accurate quote within hours.
Note: Feasibility depends on the site's structure and anti-scraping measures in place.

Technology:
Python
•
Scrapy
•
Selenium
•
Beautiful soup
•
Pandas
Technique:
Automated
Will this work on any website?
Most websites, yes — including JavaScript-heavy and dynamic sites. Some sites with heavy anti-bot protection (strict CAPTCHAs, login walls) may need extra time or aren't always possible. Send me the URL first and I'll confirm.
How do you handle IP bans or getting blocked?
I use proxies, request throttling, and header/user-agent rotation to avoid detection and keep scraping stable, especially for large or repeated jobs.
Can you scrape data behind a login?
Yes, if you provide valid credentials or access, I can automate login flows and scrape data behind them.
What format will I receive the data in?
Excel (.xlsx), CSV, JSON, or synced directly to Google Sheets — whatever works best for you.
Do I get the scraper's source code?
Yes, available as an add-on. I provide clean, commented Python code so you can run or modify it yourself later.
How do you handle large-scale scraping (10,000+ records)?
I use asynchronous requests, batching, and proxy rotation to scrape at scale without crashing or getting blocked, with built-in error handling and retries.
Is web scraping legal?
I only scrape publicly available data and follow each site's terms of service where applicable. I don't bypass paywalls or extract private/personal data without consent.