Browse categories
English
$
USD
Connect to your AI
Make routine document and folder work easier to repeat.
I will build a local Python workflow to extract existing text from digital PDFs, inventory a directory, identify identical content, or create an organized folder copy using agreed rules.
Outputs can include a TXT per document, page-level JSON, a status CSV, and an inventory with relative paths, sizes and SHA-256 fingerprints. Blank pages or those without extractable content are flagged.
The organizer creates a reviewable plan first. Explicit copy mode preserves originals and verifies the results. It does not move or delete your source material.
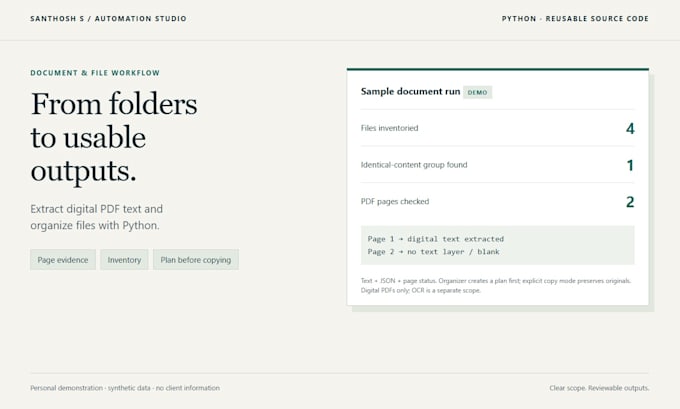
You receive reusable code, run instructions, sample outputs and a summary. My personal demo uses synthetic data: four items inventoried and a two-page sample checked, including one blank page.
Scans, OCR, handwriting, table reconstruction, locked documents and web scraping need separate scoping. Reading order depends on the original structure.
Premium includes one Windows setup walkthrough and 14 days of delivered-scope defect fixes.
Send a sanitized sample, counts, total size and your required output before choosing a package.
Senior Executive
Languages
Can you process scanned PDFs or images?
This package covers digital PDFs with an existing text layer. Scans and handwriting need a separately scoped OCR workflow. Pages without text are flagged rather than guessed.
Will tables and the original PDF layout be preserved?
No. The output is extracted text with page evidence. PDF reading order varies, and table reconstruction or layout preservation requires a separate sample-based scope.
Will the organizer move or delete my files?
No. The default run produces a plan. An explicit copy run creates organized copies and verifies content hashes; originals are preserved. Duplicate content is reported only.
Can I rerun the automation?
Yes. Python source and a run guide are included. Inputs must retain the agreed structure, and each run writes into a new or empty output folder.
What organization rules are included?
Premium covers grouping by extension or modified UTC month while keeping the original relative folder structure. Business-specific classification or PDF field extraction is separately scoped.
What files should I share?
Send a sanitized representative sample and counts first. Supply unlocked PDF copies. Do not send passwords or unnecessary personal data. We confirm scope before processing the full batch.
What are the file, page and size limits?
Basic: 20 PDFs/100 pages/50 MB. Standard: 100 PDFs/500 pages/200 MB plus 1,000 inventory files. Premium: 200 PDFs/1,000 pages/300 MB plus 5,000 inventory files and up to 2 GB of copies. Both PDF count and combined-page limits apply.
