Browse categories
Explore
Fiverr Pro
English
$
USD


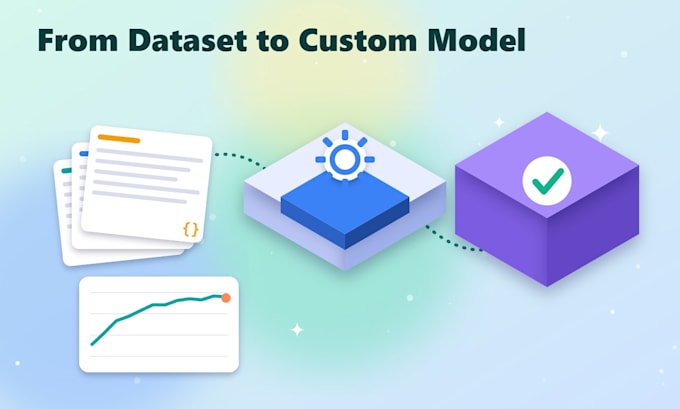
Need an open-source LLM that really knows your domain, format or style? I will fine tune it on your data and show you, with numbers, how much better it got.
I am an AI researcher (ICML 2026, IJCNLP-AACL 2025) and I fine tune and evaluate open models on multi-GPU H100 setups as part of my research.
What you get:
Models: Llama, Qwen, Mistral, Gemma, DeepSeek and other Hugging Face models.
Message me your dataset and goal before ordering and I will suggest the right base model, method and package.
AI Safety Researcher and LLM Fine Tuning Expert
Languages
What data format do you need?
JSONL, CSV or Parquet with instruction and response pairs (or prompt and completion). If your data is raw or messy, I can help clean and format it first.
Do I need my own GPUs?
No. I can run training on cloud GPUs, with compute costs agreed upfront, or train on your own cloud account or hardware if your data must stay with you.
How much data do I need?
For style or format tasks a few hundred good examples can be enough. For new domain knowledge or harder tasks, a few thousand is better. If you have less, I can help you build or augment a dataset.
Will I own the fine-tuned model?
Yes. You get the adapter or merged weights, the training code and the config. Your data and model stay private and are not reused for anyone else. Usage is subject only to the base model's own license.