Browse categories
Explore
Fiverr Pro
English
$
USD

Worried your AI chatbot or LLM app could leak sensitive data, produce unsafe output, or be manipulated by abusive user input? I'll harden it against the OWASP LLM Top 10 risks defensively, methodically, with a clear remediation report.
I will perform a defensive AI safety and assurance review of YOUR OWN LLM application or chatbot:
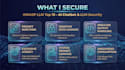
OWASP LLM Top 10 risk review (LLM01 to LLM10)
Guardrail and input-handling assessment
Sensitive-data leakage and output-filter review
RAG / document-ingestion safety check (indirect-input risks)
Rate-limiting and resource-abuse exposure review
Written PDF report with risk ratings, evidence, and fixes
WHY ME:
Built a production AI safety gateway from scratch (public on GitHub)
Research background in AI safety and cloud-native engineering
Maps findings to OWASP LLM Top 10, NIST AI RMF, ISO 42001
Defensive review only your system, your authorization
STANDARDS & TOOLING:
OWASP LLM Top 10, NIST AI RMF, MITRE ATLAS, ISO 42001, promptfoo, Garak
SUPPORTED PLATFORMS:
OpenAI, Anthropic Claude, Groq, Llama (Ollama), Mistral, Gemini, custom RAG, AI agents, chatbots
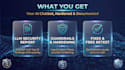
YOU GET:
PDF executive-summary report
Detailed findings with severity ratings
Concrete fix recomme
Cloud Native Security and DevSecOps Engineer, Kubernetes CI CD AI Safety
Languages
Q1: Will you actually try to "break into" my AI?
No. I perform a defensive safety and assurance review using the OWASP LLM Top 10 methodology on systems you own or are authorized to assess. I do not perform offensive testing of any kind.
Q2: What types of AI apps do you support?
Chatbots, customer-support assistants, RAG applications, AI agents, and internal AI tools. OpenAI, Anthropic, Groq, Ollama, Mistral, and Gemini are all supported.
Q3: What does the final report look like?
A PDF with an executive summary plus detailed findings. Each finding includes: OWASP LLM category, severity rating, supporting evidence, and a concrete fix recommendation.
Q4: Can you also fix the issues you find?
Yes — the Premium package includes guardrail and input-filter implementation. The Standard package provides recommendations only.
Q5: How long does it take?
Basic: 3 days. Standard: 7 days. Premium: 14 days. Faster turnaround possible — message me before ordering.
Q6: Is this confidential?
Yes. I will sign an NDA before reviewing anything sensitive. All credentials and inputs you share are destroyed after the engagement.


