Browse categories
English
$
USD
Connect to your AI
Python AI Engineer for MCP, Claude Code and Computer Vision
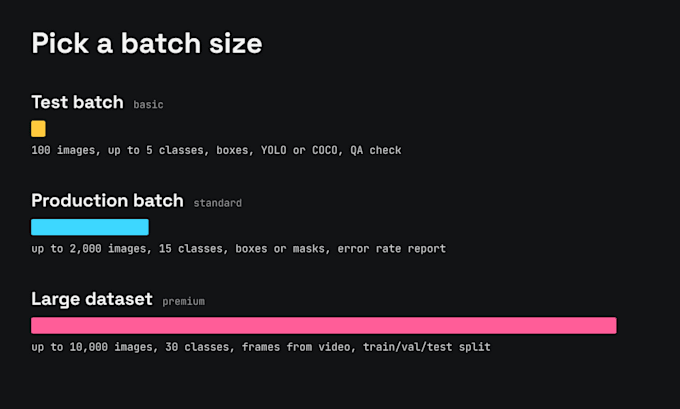
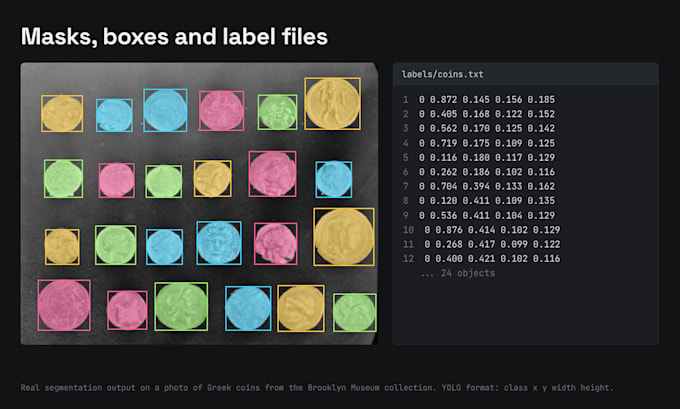
Labeling images by hand gets slow and expensive once a dataset passes a few hundred images. I use vision models such as SAM 2 and Grounding DINO to pre-label your images or video frames, then I check a random sample by hand and tell you the error rate I found.
You get bounding boxes or segmentation masks for your classes, exported in YOLO, COCO or Pascal VOC format, in a folder structure you can train on right away. I can also split the data into train, validation and test sets.
Since I build Python image and video pipelines, I can take care of the prep work too: pulling frames out of video, removing near duplicate images and cleaning up file names.
AI pre-labeling works best when objects have clear edges. If you're not sure your data fits, start with the 100 image test batch, or message me a few samples first and I'll tell you what to expect.
Technique:
Automated
Tagging type:
Image
•
Video
Which formats do you deliver?
YOLO (txt), COCO (JSON) and Pascal VOC (XML). Ask me if you need another format.
How accurate are AI pre-labels?
It depends on how distinct your objects are. I review a random sample by hand, correct the labels I check, and report the error rate so you know what you're getting.
Can you label video?
Yes. I extract frames at the rate you choose and label those frames.
What happens to my images?
They're used only for your order and deleted after delivery if you ask.
Can you train a model on the labeled data?
Yes. Message me for a custom offer to train a YOLO model on your dataset.