Browse categories
Explore
Fiverr Pro
English
$
USD
Machine Learning Engineer
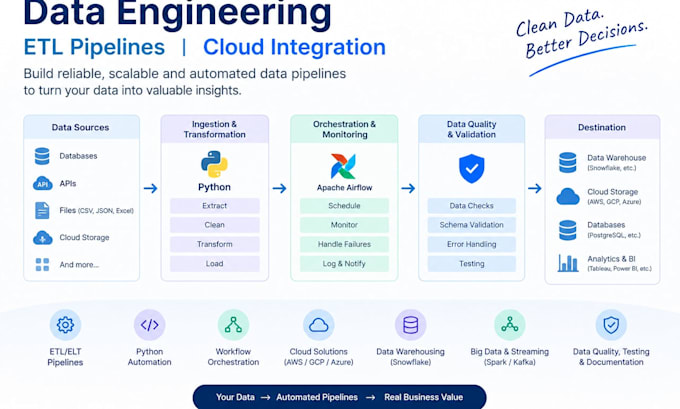
Need reliable and scalable data pipelines for your business?
I will build custom data engineering solutions to automate workflows, improve data quality, and streamline data processing.
My services include:
What you get:
I focus on building practical solutions tailored to your requirements and existing infrastructure.
Please share your data sources, expected output, data volume, and preferred technologies before ordering. Complex projects may require a custom offer.
Tools & Platforms:
Other
What information do you need before starting a project?
I need your project requirements, data sources, expected output, approximate data volume, processing frequency, and preferred tools or cloud platform. Sample or anonymized data and existing code are helpful where applicable.
Which technologies and platforms do you support?
I work with Python, SQL, ETL/ELT workflows, Apache Airflow and similar orchestrators, Apache Spark, Kafka, Snowflake, Databricks, and cloud platforms such as AWS, Google Cloud, and Azure. The exact technology stack depends on the project scope.
Can you work with my existing data pipeline or codebase?
Yes. I can help troubleshoot, modify, optimise, or extend an existing pipeline. Please share the current architecture, relevant code, error details, and desired outcome so I can assess the scope before work begins.
Do your packages include cloud deployment?
Cloud deployment is included only when explicitly specified in the selected package or purchased as an extra. Cloud usage charges, third-party subscriptions, and additional infrastructure costs are not included in my service price.
Can you build real-time data streaming pipelines?
Yes, for clearly defined use cases. Streaming integrations can be included in the applicable package or purchased as an extra. Complex Kafka clusters, high-throughput systems, and extensive infrastructure setup may require a custom offer.
What if my project requires more work than the package includes?
I will review your requirements and clarify the scope before starting. If your project needs additional data sources, complex transformations, extra integrations, or infrastructure beyond the selected package, I can propose a custom offer with an agreed price and delivery timeline.
