Browse categories
English
$
USD
Connect to your AI
AI Engineer, LLM, RAG and NLP Developer
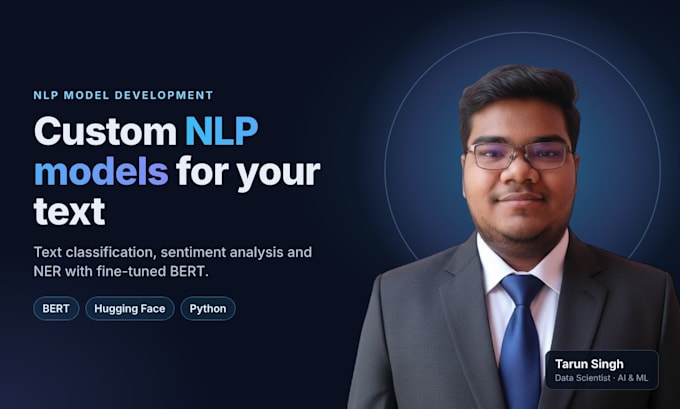
Need a model that understands your text: reviews, support tickets, emails, comments or documents?
I build and fine-tune NLP models with BERT, RoBERTa and DistilBERT that turn raw text into accurate predictions.
What I can build:
What you get:
Why me?
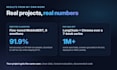
I'm a Data Scientist working on NLP and LLMs every day. I fine-tuned MobileBERT to 91.9% accuracy on 6-class emotion detection, then halved its size with quantization while keeping 91.1%. At work, I build LangChain LLM pipelines and FastAPI services that run in production.
Message me with your data and goal before ordering, and I'll suggest the right package.
Programming language:
Python
•
SQL
•
Colab
•
NoSQL
•
MLflow
Frameworks:
Scikit-learn
•
Keras
•
PyTorch
•
Panda
Tools:
Jupyter Notebook
•
TensorFlow
•
Excel
•
MLflow
•
Colab
What data do I need to provide?
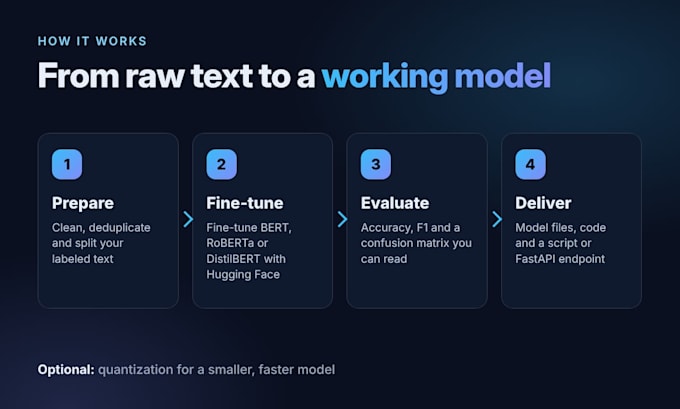
A CSV or Excel file with your text and labels works best. No labels yet? I can suggest a labeling plan or use zero-shot and LLM-based methods to get you started.
Which models do you use?
BERT, RoBERTa, DistilBERT or MobileBERT, and open-source LLMs like Llama or Mistral through Hugging Face. I pick the smallest model that meets your accuracy and speed needs.
Can you guarantee a specific accuracy?
Nobody can honestly promise accuracy before seeing the data. I share a baseline early, explain the results clearly and improve the model within your package revisions.
Will I be able to run the model myself?
Yes. You get the trained model files, the code and a simple inference script. Standard adds a FastAPI endpoint, and Premium adds Docker and cloud deployment.
Do you work with languages other than English?
Yes. I use multilingual models such as XLM-RoBERTa and mBERT, including Hindi and other Indian languages.
Is my data kept private?
Your data is used only for your project and is never shared. I delete my copies after delivery if you ask.