Browse categories
Explore
Fiverr Pro
English
$
USD


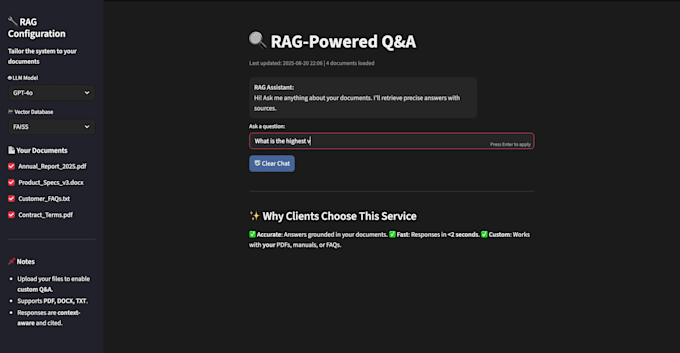
Are you looking to supercharge your AI applications with Retrieval-Augmented Generation (RAG)? Youre in the right place!
I will design and implement a production-ready RAG pipeline that combines the power of Large Language Models (LLMs) with intelligent retrieval systems, enabling your AI to provide accurate, context-aware, and up-to-date responses.
What I Offer:
End-to-End RAG Pipeline Development (retriever + generator)
Integration with vector databases (Pinecone, Weaviate, FAISS, Milvus, etc.)
Document ingestion & chunking with embeddings
API-ready deployment (FastAPI/Flask)
Fine-tuning for domain-specific use cases
Explainable AI integration for transparency
Optimization for scalability & latency
Use Cases:
Why Choose Me?
As an expert ML/AI engineer and Python developer, Ive built real-world RAG solutions that are scalable, flexible, and tailored to business needs. I ensure clean, documented, and production-ready code so you can scale with confidence.
Hi, I'm Tauseef Ahmed, an AI ML engineer with 7 years of experience
Languages
What is a RAG solution?
A RAG (Retrieval-Augmented Generation) solution combines a retriever (fetching relevant knowledge from a database) with a generator (LLM like GPT) to deliver accurate, context-aware, and reliable responses.
Why do I need RAG instead of a normal LLM?
Standard LLMs can hallucinate or give outdated answers. With RAG, your AI has access to real-time, domain-specific knowledge, ensuring correctness, trustworthiness, and reduced hallucinations.
Which vector databases do you support?
I support Pinecone, Weaviate, FAISS, Milvus, Chroma, and ElasticSearch. If you have another one in mind, I can integrate it as well.
Can you deploy the solution to production?
Yes! I can deploy your RAG pipeline as an API (FastAPI/Flask), integrate it into chatbots or web apps, and set it up for scalability in cloud environments (AWS, GCP, Azure, etc.)(Specific Plan only).
Do I need my own LLM or can we use OpenAI/others?
Both are possible! I can integrate OpenAI, Anthropic, Cohere, HuggingFace models, or your own fine-tuned LLM depending on your needs.
Can you make it domain-specific (legal, medical, financial, etc.)?
Absolutely ✅. I can fine-tune embeddings, retrieval logic, and pipeline setup for domain-specific applications, ensuring your RAG solution fits your industry.
How do you ensure data privacy and security?
I use secure pipelines, private vector stores, and access-controlled APIs to protect your sensitive data. Deployment can be done on your servers or cloud accounts for full control.
What do I need to get started?
Just share your requirements, available data (documents, knowledge base, etc.), and preferred tech stack. I’ll guide you through the rest!