Browse categories
English
$
USD
Connect to your AI
Data Analyst and Data Scientist
I build classification, regression and clustering models for tabular data in Python. R is available by agreement.
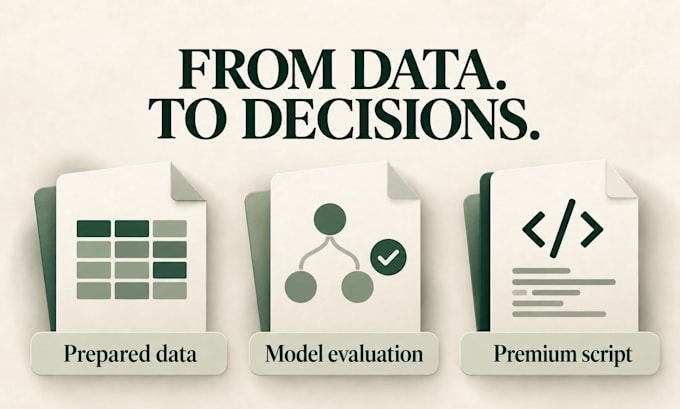
Included: exploratory data analysis (EDA), agreed cleaning and preprocessing, model training, evaluation and optimization. You receive commented code, documentation and clear explanations of results and limitations.
Each package covers 1 table and 1 prediction target or clustering question:
Input columns are counted before encoding; the target column is additional where applicable. Your data does not need to be model-ready.
Formats: CSV, Excel or SPSS (.sav).
Message me before ordering with your goal, file format, dimensions and an anonymized sample. We confirm feasibility and preprocessing scope first. Table merging, manual data reconstruction and database extraction require a separate quote.
Portfolio example: LearnerCue
https://tonywillert.github.io/Portfolio/#learnercue


Programming language:
Python
•
R
•
SQL
•
NoSQL
Frameworks:
Scikit-learn
•
Keras
•
PyTorch
•
Panda
Tools:
Jupyter Notebook
•
TensorFlow
•
Excel
•
RStudio
What machine learning tasks do you offer?
I build classification, regression and clustering models for structured, tabular data. Typical goals include predicting an outcome, estimating a value or identifying groups. Each order covers one agreed prediction target or clustering question.
Does my data need to be cleaned first?
No. Your data should be a structured table, but it does not need to be model-ready. EDA and agreed preprocessing are included within package limits, such as cleaning, handling missing values, encoding categories and scaling features.
How are the package limits counted?
Each package covers one table. Limits: Basic 2,000 rows/10 input columns; Standard 10,000/20; Premium 30,000/30. Headers do not count as rows. Input columns are counted before encoding; a target column is additional when needed.
What will I receive with each package?
All packages include commented code, evaluation results and documentation. Basic covers one algorithm; Standard and Premium up to three. Premium adds a reusable prediction script and guide for data with the same structure. Repeated fits during tuning count as the same algorithm.
Which file formats and languages do you support?
I accept CSV, Excel (.xlsx) and SPSS (.sav). Python is the default; R is available by agreement. A data dictionary is helpful. Database extraction, table merging and manual data reconstruction require a separate scope and quote before ordering.
Can you guarantee a specific accuracy?
No specific score or business outcome is guaranteed. Performance depends on data quality, available information and the task. We assess feasibility before ordering. I use appropriate validation and explain the measured performance and limitations.
What does a revision include?
A revision is one consolidated round of adjustments within the agreed scope. Basic and Standard include one; Premium includes two. New analyses, datasets, targets or deliverables need a separate quote. Errors in implementing the agreed work are corrected.
Are deployment and ongoing maintenance included?
The packages cover model development and handover. Cloud deployment, API integration, scheduled runs, ongoing monitoring and maintenance are outside scope. Fine-tuning pretrained models is also separate. Please discuss these requirements before ordering.
What should I send before ordering?
Send your goal, file format, row and column counts, column descriptions and a small synthetic or fully anonymized sample you are allowed to share. We confirm feasibility, preparation needs, suitable files and the transfer method before work starts.