Browse categories
English
$
USD
Connect to your AI

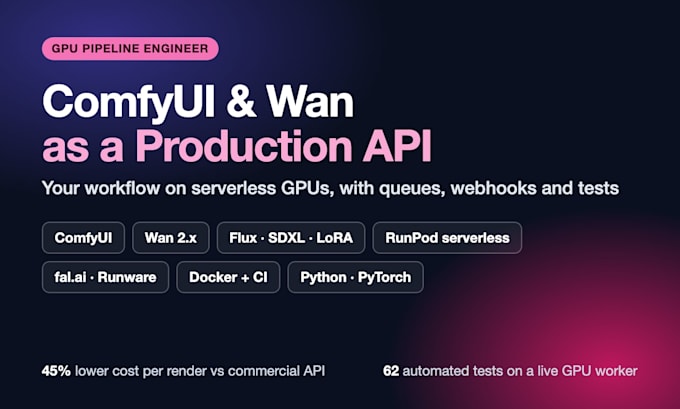
Have a ComfyUI workflow that works on your desktop but need it running as a reliable API for your app, agency or SaaS?
I turn ComfyUI, Wan, Flux and Stable Diffusion workflows into production services: serverless GPU workers on RunPod, or hosted inference through fal.ai and Runware when you want zero infrastructure.
What I build:
Proof: a self hosted avatar rendering worker I built has 62 automated tests and cut cost per render by about 45% versus the commercial API, with automatic fallback.
Stack: Python, Docker, RunPod, ComfyUI, PyTorch, Node.js, Supabase.
Message me first with your workflow or model and I will reply with a plan and a fixed quote.
AI Developer for AI Agents, n8n Automation, Claude Code and GenAI Video
Languages
Can you host it for me or do I need my own GPU account?
It runs in your own RunPod, fal.ai or Runware account so you own the keys, data and billing. I set everything up, hand over the Docker image and endpoint, and show your team how to update models.
Which models and workflows do you support?
ComfyUI graphs with any custom nodes, Wan 2.x text and image to animation, Flux, SDXL, LoRA, ControlNet, upscalers, background removal and talking avatar models. If it runs in ComfyUI or on Hugging Face, I can serve it.
How do you keep GPU costs down?
Serverless workers that scale to zero, tuned cold starts with baked in models, batching and caching, spot GPUs where safe, and a fallback to a hosted provider like fal.ai so you never lose a job. You see cost per render in the logs.