Browse categories
English
$
USD
Connect to your AI
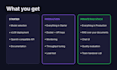
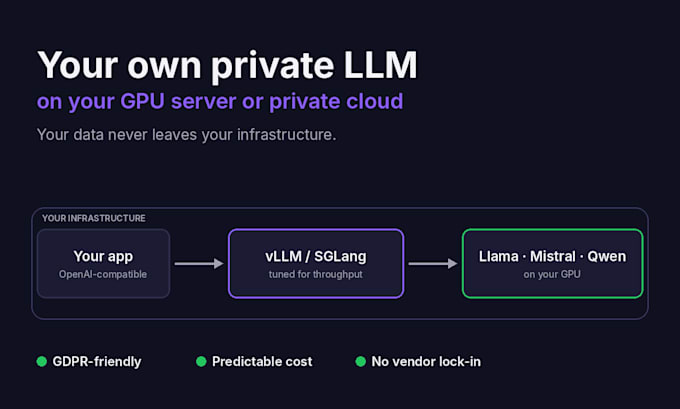
Want ChatGPT-level AI without sending your data to OpenAI? I'll deploy an open-source LLM on your own GPU server or private cloud, so prompts and documents never leave your infrastructure.
I'm an AI engineer who built and ran a sovereign AI platform in production for a Dutch hosting company with 1.4M+ subscriptions. This is real inference engineering, not a one-click Ollama install.
What I do:
Pick the right model for your task and hardware (Llama, Mistral, Qwen, DeepSeek, Gemma)
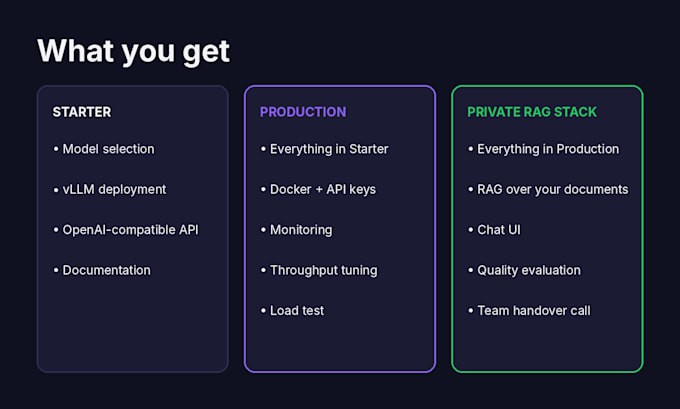
Deploy it with vLLM or SGLang behind an OpenAI-compatible API, so your existing code just works
Tune throughput, latency and GPU memory (quantization, KV cache, batching)
Add Docker, API keys, monitoring and load testing for real traffic
Optional: RAG over your own documents with a chat UI
Good fit if you:
Have privacy, GDPR or compliance requirements
Pay too much for API tokens and want predictable costs
Already have GPUs (on-prem, RunPod, Lambda, AWS, Hetzner) or need help choosing them
Please message me before ordering with your use case and hardware, so I can confirm the right package.
Senior AIML Engineer
Languages
Do I need my own GPU?
You need access to a GPU server: on-prem, or rented from providers like RunPod, Lambda, AWS or Hetzner. If you don't have one yet, I'll recommend the right GPU and provider for your model and budget before you order.
Will it work with my existing OpenAI code?
Yes. The deployment exposes an OpenAI-compatible API, so in most cases you only change the base URL and model name in your code.
Which model should I use?
It depends on your task, language and GPU memory. I recommend a model (e.g. Llama, Mistral, Qwen, DeepSeek or Gemma) and quantization level so you get the best quality your hardware can run fast.
How do you access my server?
Through a temporary SSH user or cloud account with only the permissions needed. You can remove my access as soon as the work is delivered.
Will a self-hosted model be as good as GPT-4?
For focused tasks like document Q&A, summarization or classification, modern open models are often close enough. For broad reasoning they can lag behind. I'll tell you honestly what to expect for your use case before we start.