Browse categories
Explore
Fiverr Pro
English
$
USD

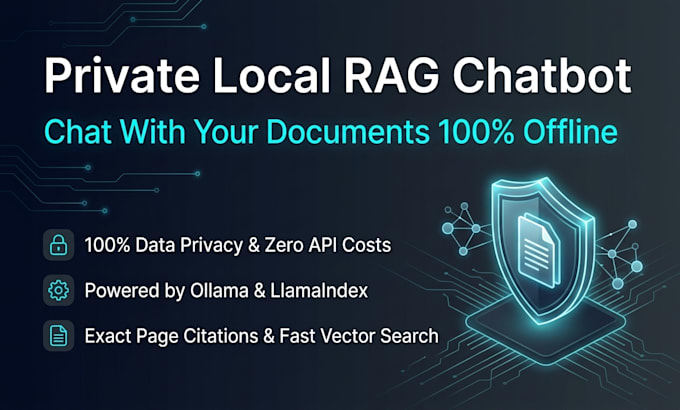
Are you working with confidential documents, legal contracts, or proprietary company data that cannot be uploaded to cloud APIs like OpenAI or Anthropic?
I will build a 100% Private, Offline RAG (Retrieval-Augmented Generation) System that allows you to chat with your documents locally on your laptop or private server. Zero API keys, zero cloud latency, and complete data privacy.
What You Get:
Tech Stack Used:
Keep your data completely secure while unlocking the full power of conversational AI over your private files!
Data Science and AI Engineer
Languages
Do I need an internet connection to run this chatbot?
No! Once installed, the entire RAG system runs completely offline on your machine with zero external network requests.
What hardware do I need to run this locally?
A system with 8GB RAM can easily run 3B/7B quantized models (like Qwen 2.5 or Llama 3.1). For optimal performance, a discrete GPU (NVIDIA RTX series) is recommended.
Can this handle large PDF files with hundreds of pages?
Yes. The system chunks and embeds your documents into a local vector database, allowing instant retrieval regardless of total page count.
