Browse categories
Explore
Fiverr Pro
English
$
USD


Thinking about running AI locally on your own PC or server, but not sure where to start?
Running models locally protects your data, eliminates cloud fees, and gives you total control. But figuring out VRAM limits, CUDA drivers, tensor splitting, and tools like Ollama, llama.cpp, or Open WebUI can be frustrating.
I am an independent Systems Engineer specializing in local AI deployment and hardware optimization. I help homelabbers, creators, and small businesses build self-hosted AI setups on their existing hardware.
In our 30-minute consultation, we'll cover:
Hardware Assessment: Evaluating your CPU, VRAM, and RAM limits.
Model Selection: Finding the best text, voice, or image models for your rig.
Software Stack: Choosing the right backend (Ollama, llama.cpp, LM Studio).
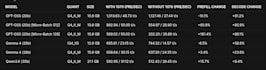
Optimization: Fixing slow generation speeds, CUDA errors, and OOM crashes.
What I need: Just your PC specs and your project goals!
Jack of all Tech
Languages
Do I need an expensive $2,000+ GPU to run AI locally?
Absolutely not. Many powerful open-source models can run on standard consumer GPUs, older hardware, or even CPU system RAM with proper optimization. I will help you squeeze the maximum performance out of what you already own.
What hardware information do I need to provide for the consultation?
Just let me know your CPU model, total System RAM (e.g., 16GB or 32GB), and your GPU model and VRAM capacity (e.g., RTX 3060 12GB).
Can you help with image generation (Stable Diffusion) and voice AI as well?
Yes! I consult on text models (LLMs), voice/audio pipelines (Speech-to-Text / Text-to-Speech), and local image generation workflows.
Do you offer hands-on remote installation or setup?
This gig covers strategy, model selection, and troubleshooting roadmaps. If you need hands-on remote setup via AnyDesk or TeamViewer, send me a message for a custom quote!


