Browse categories
Explore
Fiverr Pro
English
$
USD
Bioinformatics Virtual Knockout Molecular Dynamics RNAseq DTA
I will validate compound SMILES and protein sequences, run one existing affinity model and return matched predictions, per-row status, a ranked table and model/version notes. Basic: up to 1,000 pairs and 20 proteins.
Available routes: bilinear DTA, DeepDTA, GraphDTA, and a MolTrans-derived ChemBERTa cross-attention variant with a length-mask repair.
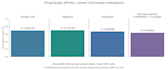
Our saved records use BindingDB Ki/Kd-derived pKi/pKd labels, frozen NPZ splits and cold-target evaluation (test proteins held out of training). Concordance indices: bilinear 0.695145; DeepDTA 0.702238; GraphDTA 0.668996; repaired MolTrans-derived variant 0.636565. These are route-specific checkpoint records, not one shared-test comparison.
Send CSV columns sample_id, smiles and protein_sequence; add compound_id/target_id if available. Confirm model and ranking per target. Predictions support candidate prioritization.
Weights and runnable deployment packages may be supplied by separate agreement after asset and distribution checks. Multiple models, retraining and new validation splits are separate scopes. Message me before ordering.

Expertise:
Ranking
•
Predictive analysis
Programming language:
Python
Frameworks:
PyTorch
